
Evaluation Overview
Why evaluate your agent
Section titled “Why evaluate your agent”LLM agents fail in production in ways you can't predict upfront. A prompt that works for 90% of queries might hallucinate on edge cases, ignore context, or produce verbose responses when users expect concise answers. Manual review doesn't scale, and you can't anticipate every failure mode before shipping.
You need automated regression testing — but not the kind where you sit down and write a test suite from scratch. The most effective test suites are built incrementally, from real production failures. Every time you find a bad response, you turn it into a test case. Over time, your suite becomes a comprehensive guard against the specific failure modes your agent actually encounters.
The evaluation loop
Section titled “The evaluation loop”Find an issue in production
Start in the Opik dashboard. Browse traces, filter by error status or low feedback scores, and click into a trace to see the full span tree — every LLM call, tool invocation, and retrieval step with its inputs, outputs, and latencies.
Add it to a test suite
Turn the failure into a test case. Add the trace to a test suite with a natural-language assertion that captures the expected behavior — for example, "The response must not hallucinate facts not present in the context". You can do this through Ollie (Opik's AI assistant), the UI, or the SDK.
Update your agent
Fix the root cause. Update a prompt via the Prompt Library, adjust tool definitions, or change retrieval parameters. Use Ollie to help diagnose the issue and suggest fixes.
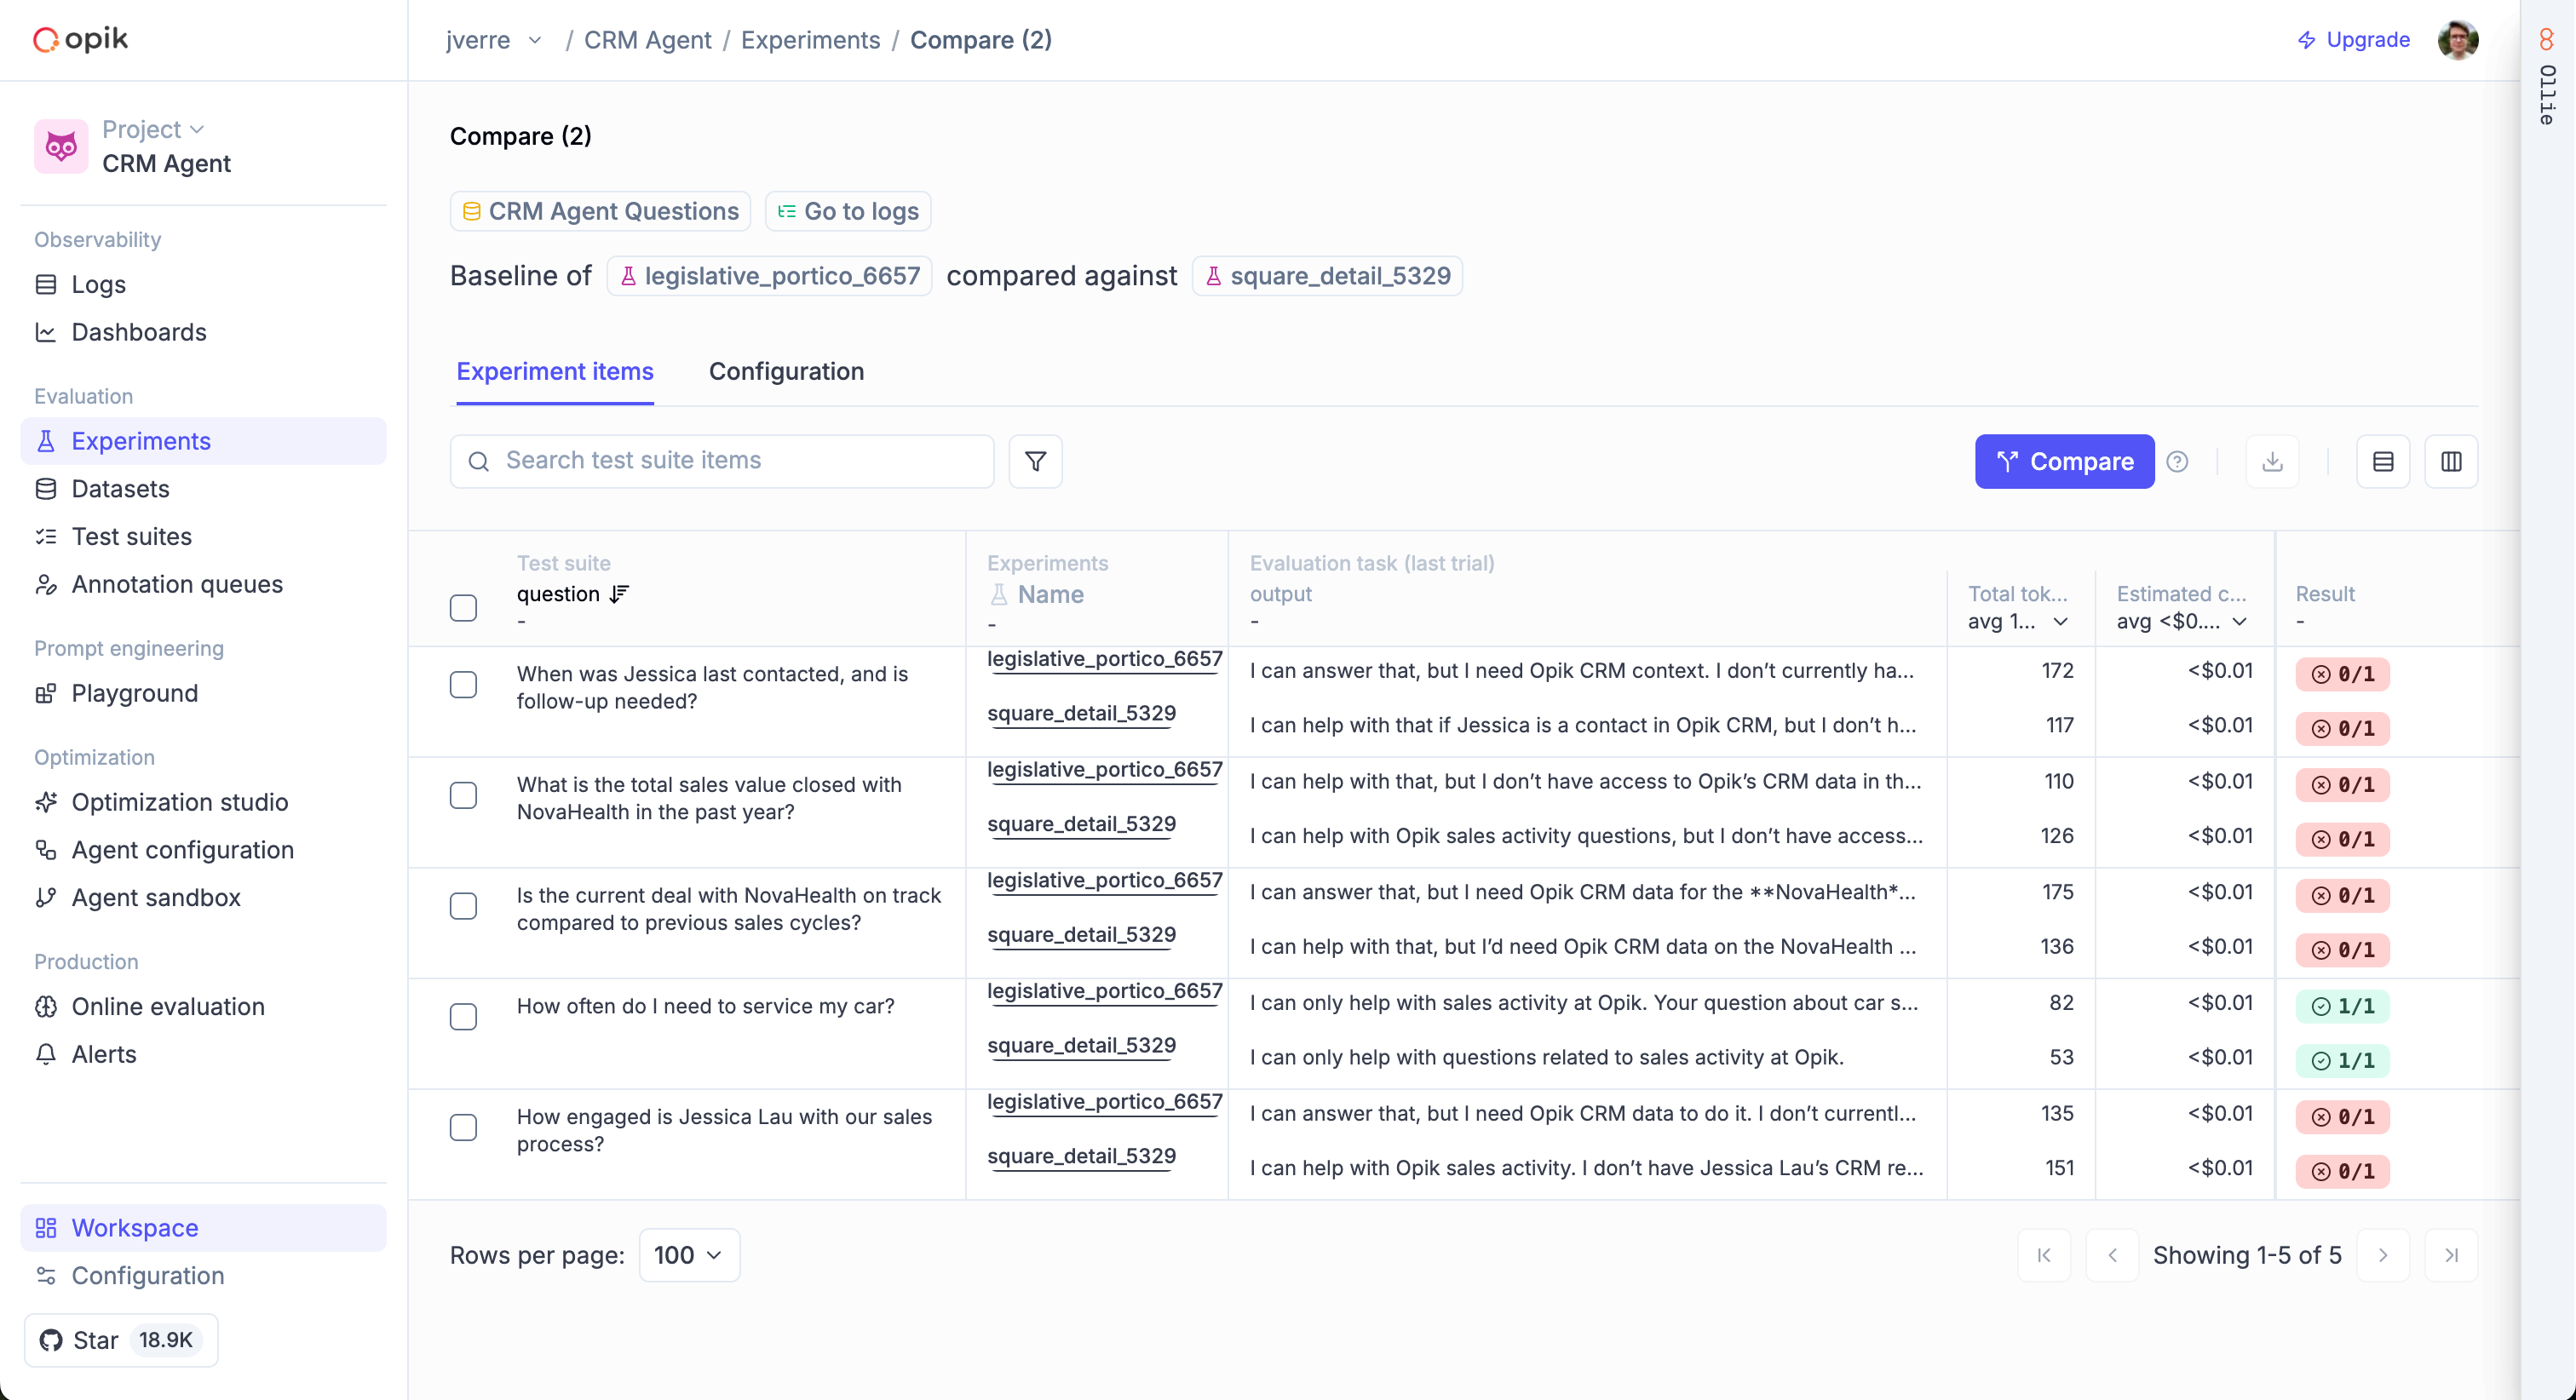
Validate with the test suite
Run the test suite against your updated agent. The suite checks every test case — including the new one — so you confirm the fix works and nothing else regressed.
Each cycle adds a new test case. Over time, your test suite becomes a comprehensive regression guard tailored to the real failure modes of your agent.
Two approaches to evaluation
Section titled “Two approaches to evaluation”Opik provides two complementary approaches to evaluation:
- Test Suites: Define natural-language assertions and let an LLM judge check them automatically. Best for pass/fail testing of specific behaviors.
- Datasets & Metrics: Score your agent's outputs against a dataset using pre-built or custom metrics. Best for measuring quality across many traces with quantitative scores.
Key features
Section titled “Key features”- Test Suites with natural-language assertions and execution policies
- 30+ pre-built metrics for hallucination, relevance, coherence, and more
- Custom metrics for domain-specific evaluation
- Experiment tracking to compare versions side-by-side
- Annotation Queues for human-in-the-loop review
Next steps
Section titled “Next steps”- Getting started — Run your first evaluation in minutes
- Concepts — Understand Test Suites vs Datasets & Metrics
- Building Test Suites — Create and manage suites via the SDK, UI, or Ollie
- Debugging agents with Ollie — The full workflow for turning production failures into test cases
- MCP server — Let your AI coding assistant add cases to a suite and run evaluations for you