
GEPA Optimizer
GepaOptimizer wraps the external GEPA package to optimize a
single system prompt for single-turn tasks. It maps Opik datasets and metrics into GEPA’s expected
format, runs GEPA’s optimization using a task model and a reflection model, and returns a standard
OptimizationResult compatible with the Opik SDK.
How it works
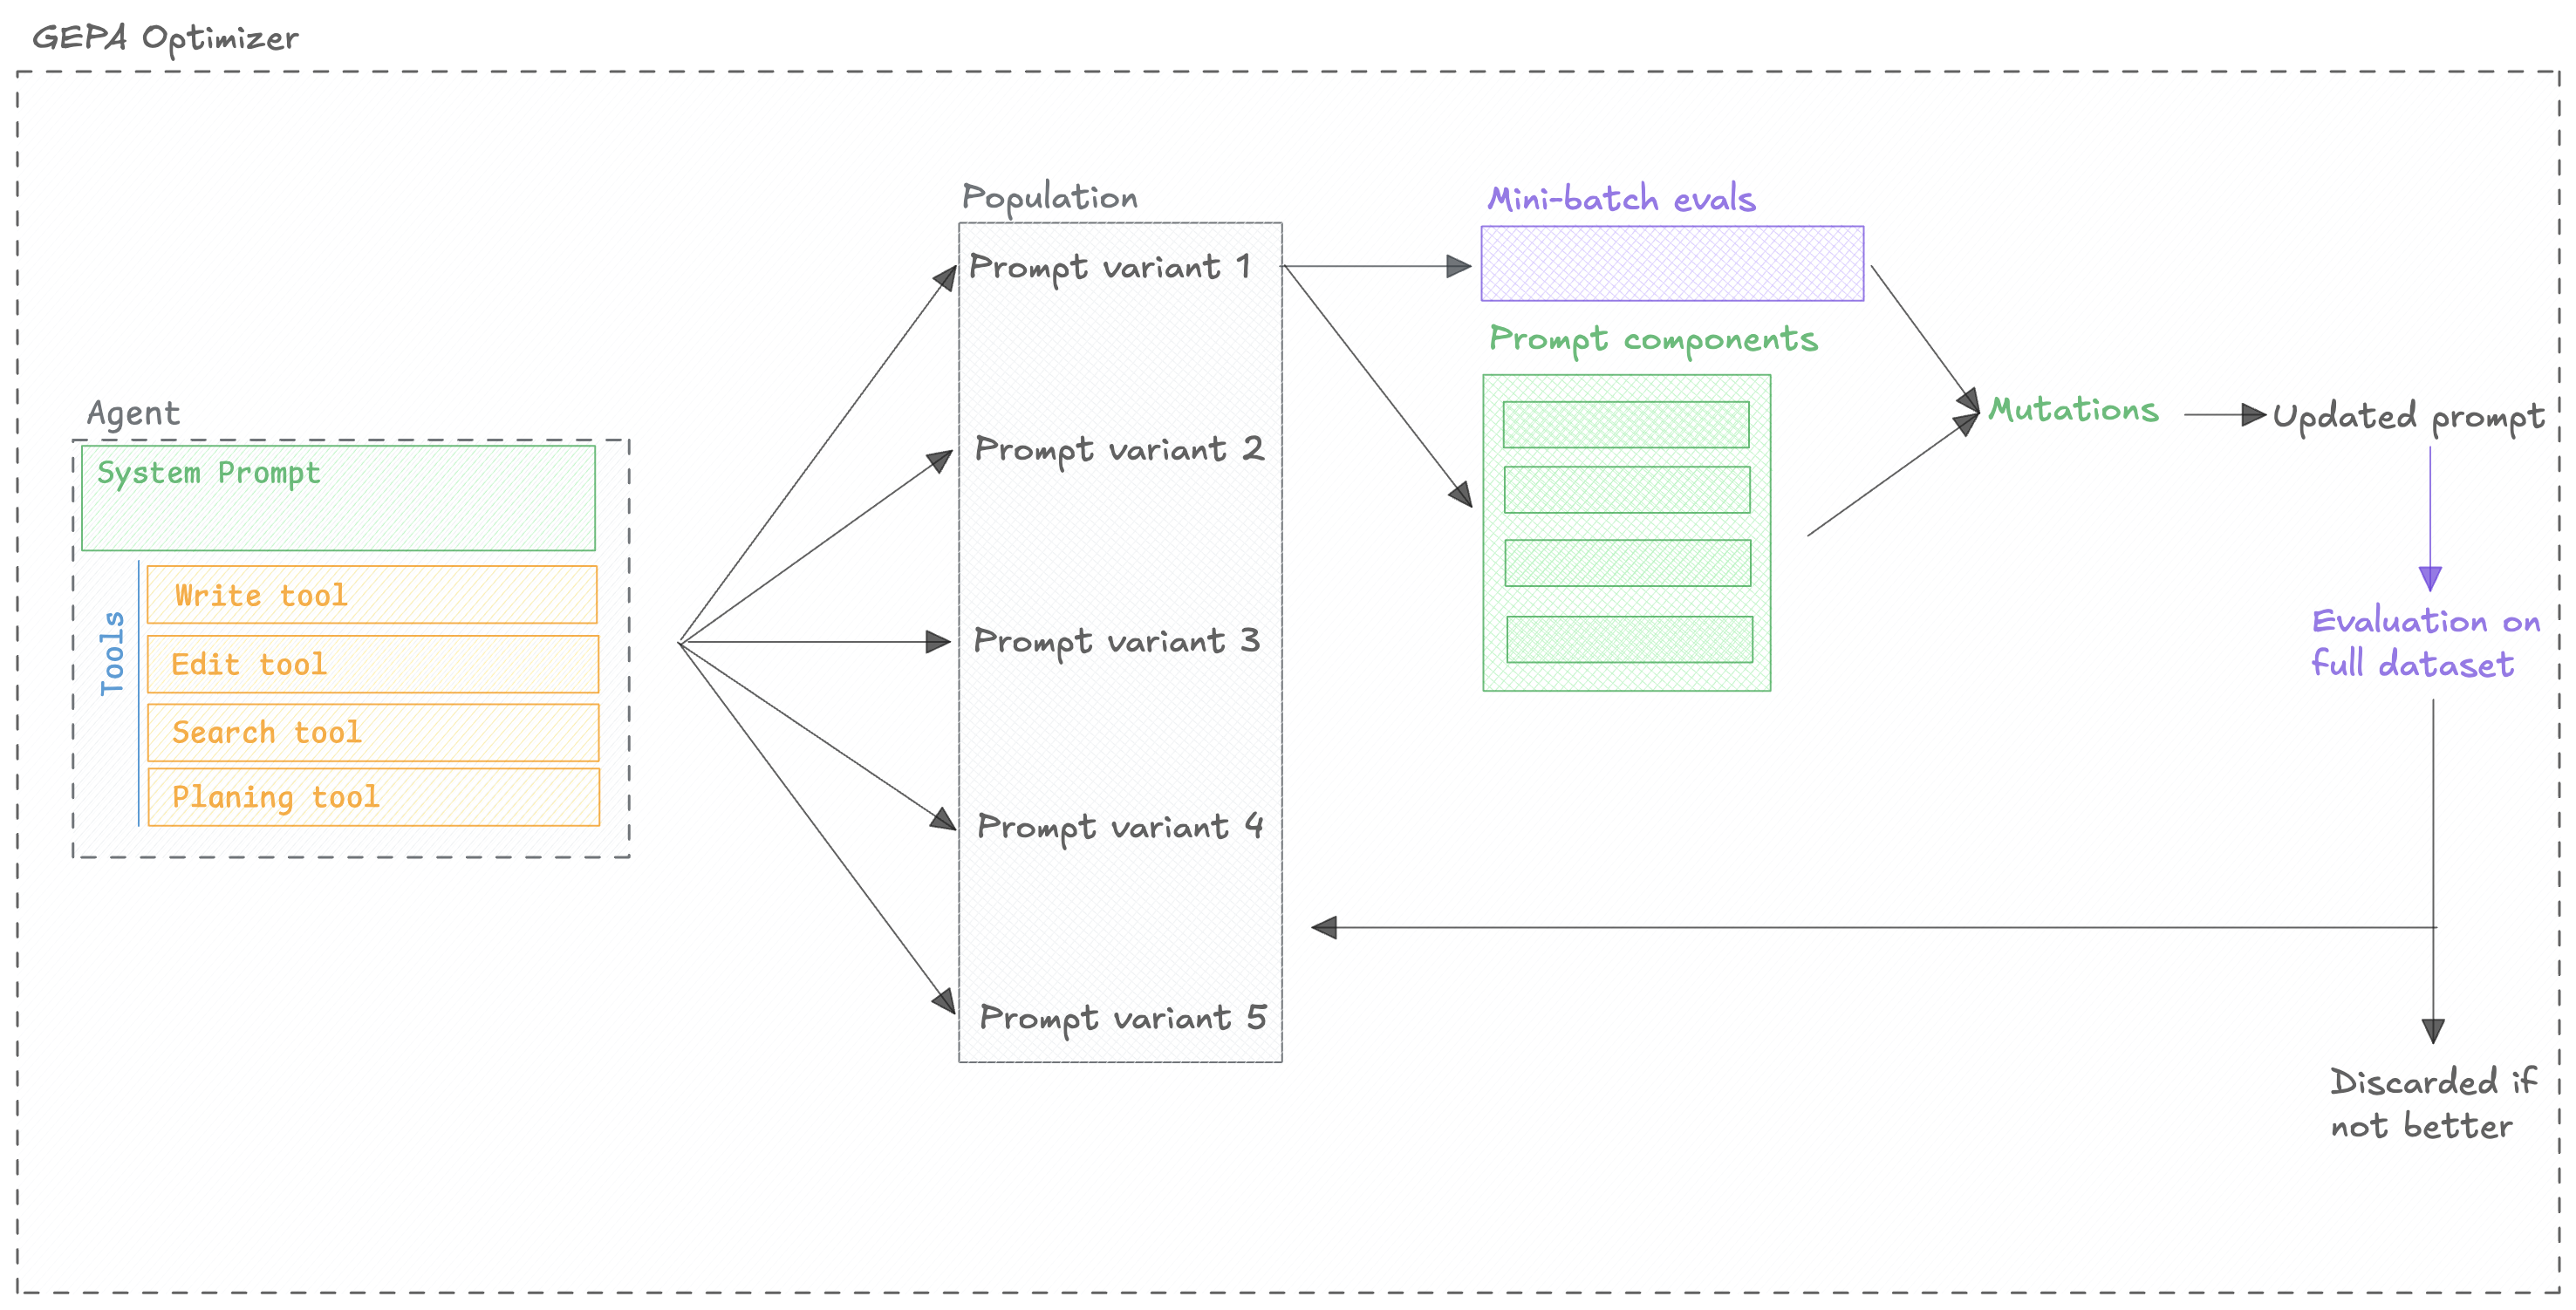
Section titled “How it works”The GEPA optimizer companies two key approaches to optimize agents:
- Reflection: The optimizer uses the outcomes from evaluations to improve the prompts.
- Evolution: The optimizer uses an evolutionary algorithm to explore the space of prompts.
You can learn more about the algorithm in the GEPA paper but in short, the optimizer will:
Quickstart
Section titled “Quickstart”"""
Optimize a simple system prompt on the tiny_test dataset.
Requires: pip install gepa, and a valid OPENAI_API_KEY for LiteLLM-backed models.
"""
from typing import Any, Dict
from opik.evaluation.metrics import LevenshteinRatio
from opik.evaluation.metrics.score_result import ScoreResult
from opik_optimizer import ChatPrompt, datasets
from opik_optimizer.gepa_optimizer import GepaOptimizer
def levenshtein_ratio(dataset_item: Dict[str, Any], llm_output: str) -> ScoreResult:
return LevenshteinRatio().score(reference=dataset_item["label"], output=llm_output)
dataset = datasets.tiny_test()
prompt = ChatPrompt(
system="You are a helpful assistant. Answer concisely with the exact answer.",
user="{text}",
)
optimizer = GepaOptimizer(
model="openai/gpt-4o-mini",
n_threads=6,
model_parameters={"temperature": 0.2, "max_tokens": 200},
)
result = optimizer.optimize_prompt(
prompt=prompt,
dataset=dataset,
metric=levenshtein_ratio,
max_trials=12,
reflection_minibatch_size=2,
n_samples=5,
)
result.display()Determinism and tool usage
Section titled “Determinism and tool usage”- GEPA’s seed is forwarded directly to the underlying
gepa.optimizecall, but any non-determinism in your prompt (tool calls, non-zero temperature, external APIs) will still introduce variance. To test seeding in isolation, disable tools or substitute cached responses. - GEPA emits its own baseline evaluation inside the optimization loop. You’ll see one baseline score from Opik’s wrapper and another from GEPA before the first trial; this is expected and does not double-charge the metric budget.
- Reflection only triggers after GEPA accepts at least
reflection_minibatch_sizeunique prompts. If the minibatch is larger than the trial budget, the optimizer logs a warning and skips reflection. - Reflection calls use
GepaOptimizer.model, are traced as Opik spans, and count toward the run's reported LLM cost. They are not metric calls, somax_trialsdoes not bound them — a run typically makes many more reflection calls than trials, because an iteration whose candidate loses on the mini-batch costs only2 * reflection_minibatch_sizemetric calls. The run reports the total asreflection_call_countin the result details; setmax_reflection_callsto cap it. - GEPA supports tool use during evaluation (
allow_tool_use=True) but does not supportoptimize_tools=Trueyet. Tool-description optimization requests are currently degraded/blocked until the adapter supports it.
GEPA scores vs. Opik scores
Section titled “GEPA scores vs. Opik scores”- The GEPA Score column reflects the aggregate score GEPA computes on its train/validation split when deciding which candidates stay on the Pareto front. It is useful for understanding how GEPA’s evolutionary search ranks prompts.
- The Opik Score column is a fresh evaluation performed through Opik’s metric pipeline on the same dataset (respecting
n_samples). This is the score you should use when comparing against your baseline or other optimizers. - Because the GEPA score is based on GEPA’s internal aggregation, it can diverge from the Opik score for the same prompt. This is expected—treat the GEPA score as a hint about why GEPA kept or discarded a candidate, and rely on the Opik score for final comparisons.
skip_perfect_score
Section titled “skip_perfect_score”- When
skip_perfect_score=True, GEPA immediately ignores any candidate whose GEPA score meets or exceeds theperfect_scorethreshold (default1.0). This keeps the search moving toward imperfect prompts instead of spending budget refining already perfect ones. - Set
skip_perfect_score=Falseif your metric tops out below1.0, or if you still want to see how GEPA mutates a perfect-scoring prompt—for example, when you care about ties being broken by Opik’s rescoring step rather than GEPA’s aggregate.
Configuration Options
Section titled “Configuration Options”Optimizer parameters
Section titled “Optimizer parameters”The optimizer has the following parameters:
-
model(str, default: openai/gpt-5-nano) — LiteLLM model name for the optimization algorithm -
model_parameters(dict[str, typing.Any] | None) — Optional dict of LiteLLM parameters for optimizer's internal LLM calls. Common params: temperature, max_tokens, max_completion_tokens, top_p. -
n_threads(int, default: 6) — Number of parallel threads for evaluation -
verbose(int, default: 1) — Controls internal logging/progress bars (0=off, 1=on) -
seed(int, default: 42) — Random seed for reproducibility
optimize_prompt parameters
Section titled “optimize_prompt parameters”The optimize_prompt method has the following parameters:
-
prompt(ChatPrompt) — The prompt to optimize -
dataset(Dataset) — Opik Dataset to optimize on -
metric(Callable) — Metric function to evaluate on -
experiment_config(dict | None) — Optional configuration for the experiment -
n_samples(int | float | str | None) — Number of dataset items to use per evaluation. Use counts (e.g.,50), fractions (e.g.,0.1), percentages (e.g., "10%"), or "all"/"full"/None for the full dataset. -
n_samples_minibatch(int | None) — Optional number of samples for inner-loop minibatches (defaults to n_samples). -
n_samples_strategy(str | None) — Sampling strategy for subsampling (default: "random_sorted"). -
auto_continue(bool, default: False) — Whether to auto-continue optimization -
agent_class(type[opik_optimizer.optimizable_agent.OptimizableAgent] | None) — Optional agent class to use -
project_name(str, default: Optimization) — -
max_trials(int, default: 10) — Maximum number of different prompts to test (default: 10) -
reflection_minibatch_size(int, default: 3) — Size of reflection minibatches (default: 3) -
max_reflection_calls(int, default: 0) — Cap on reflection-LLM calls — the calls GEPA makes to propose new candidates, which are not metric calls and are billed on top of them. Defaults to0, meaning no cap: GEPA reflects as often as its search requires. Set a positive value to bound reflection spend; the run then stops once the cap is reached and reportsfinish_reason="reflection_budget"(a run that spent its full metric budget at the same time reportsmax_trials, since the trials are the reason it ended). Reflection calls scale with engine iterations rather than trials, so pick this from the run's reportedreflection_call_count, not frommax_trials. -
candidate_selection_strategy(str, default: pareto) — Strategy for candidate selection (choose from "pareto", "current_best", or "epsilon_greedy"; default: "pareto") -
skip_perfect_score(bool, default: True) — Skip candidates with perfect scores (default: True) -
perfect_score(float, default: 1.0) — Score considered perfect (default: 1.0) -
use_merge(bool, default: False) — Enable merge operations (default: False) -
max_merge_invocations(int, default: 5) — Maximum merge invocations (default: 5) -
run_dir(str | None) — Directory for run outputs (default: None) -
track_best_outputs(bool, default: False) — Track best outputs during optimization (default: False) -
display_progress_bar(bool, default: False) — Display progress bar (default: False) -
seed(int, default: 42) — Random seed for reproducibility (default: 42) -
raise_on_exception(bool, default: True) — Raise exceptions instead of continuing (default: True) -
kwargs(Any) —
Model Support
Section titled “Model Support”GEPA coordinates two model contexts:
GepaOptimizer.model: LiteLLM model string the optimizer uses for internal reasoning (reflection, mutation prompts, etc.).ChatPrompt.model: The model evaluated against your dataset—this should match what you run in production.
Set model to any LiteLLM-supported provider (e.g., "gpt-4o", "azure/gpt-4", "anthropic/claude-3-opus", "gemini/gemini-1.5-pro") and pass extra parameters via model_parameters when you need to tune temperature, max tokens, or other limits:
optimizer = GepaOptimizer(
    model="anthropic/claude-3-opus-20240229",
    model_parameters={
        "temperature": 0.7,
        "max_tokens": 4096
    }
)
Reflection is handled internally; there is no separate reflection_model argument to set.
Limitations & tips
Section titled “Limitations & tips”- Instruction-focused: The current wrapper optimizes the instruction/system portion of your prompt. If you rely heavily on few-shot exemplars, consider pairing GEPA with the Few-Shot Bayesian optimizer or an Evolutionary run.
- Reflection can misfire: GEPA’s reflective mutations are only as good as the metric reasons you supply. If
ScoreResult.reasonis vague, the optimizer may reinforce bad behaviors. Invest in descriptive metrics before running GEPA at scale. - Cost-aware: Although GEPA is more sample-efficient than some RL-based methods, reflection and Pareto scoring still consume multiple LLM calls per trial. Start with small
max_trialsand monitor API usage.
Next Steps
Section titled “Next Steps”- Explore specific Optimizers for algorithm details.
- Refer to the FAQ for common questions and troubleshooting.
- Refer to the API Reference for detailed configuration options.