
Manage datasets
Datasets can be used to track test cases you would like to evaluate your LLM on. Each dataset is made up of a dictionary
with any key value pairs. When getting started, we recommend having an input and optional expected_output fields for
example. These datasets can be created from:
- Python SDK: You can use the Python SDK to create a dataset and add items to it.
- TypeScript SDK: You can use the TypeScript SDK to create a dataset and add items to it.
- Traces table: You can add existing logged traces (from a production application for example) to a dataset.
- The Opik UI: You can manually create a dataset and add items to it.
Once a dataset has been created, you can run Experiments on it. Each Experiment will evaluate an LLM application based on the test cases in the dataset using an evaluation metric and report the results back to the dataset.
Create a dataset via the UI
Section titled “Create a dataset via the UI”The simplest and fastest way to create a dataset is directly in the Opik UI. This is ideal for quickly bootstrapping datasets from CSV files without needing to write any code.
Steps:
- Navigate to Evaluation > Datasets in the Opik UI.
- Click Create new dataset.
- In the pop-up modal:
- Provide a name and an optional description
- Optionally, upload a CSV file with your data
- Click Create dataset.
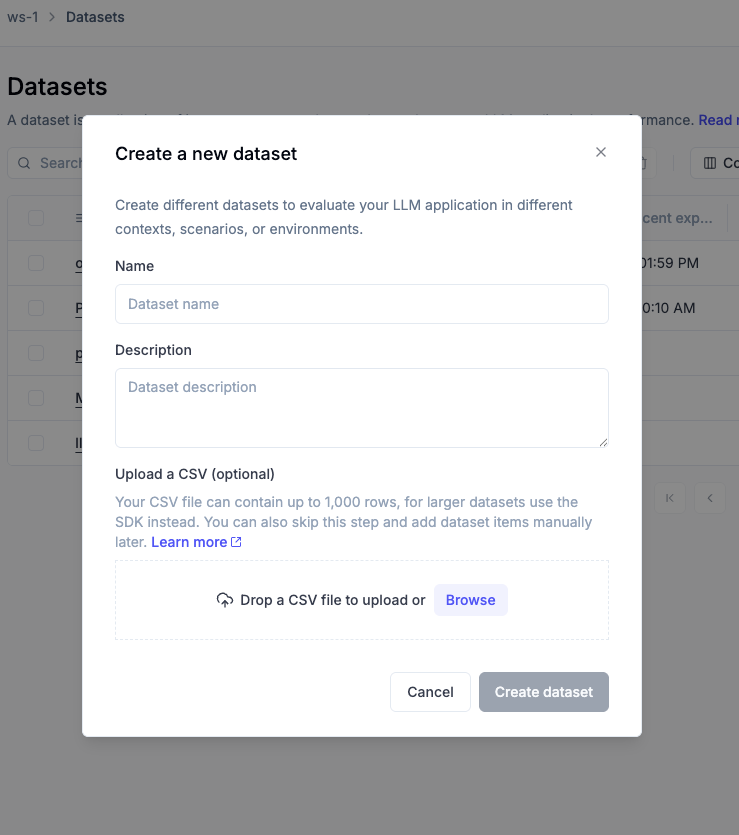
If you need to create a dataset with more than 1,000 rows, you can use the SDK.
Understanding dataset versioning
Section titled “Understanding dataset versioning”Dataset versioning in Opik creates immutable snapshots of your data. Every time you modify a dataset—whether adding, editing, or deleting items—a new version is automatically created. This ensures complete reproducibility, provides an audit trail of all changes, and allows easy rollback to any previous state.
Each dataset version contains:
- Version name: Auto-generated sequential name (v1, v2, v3, etc.)
- Change description: Optional note describing what changed
- Tags: Labels for categorizing versions (e.g.,
production,baseline) - Item statistics: Count of items added, modified, and deleted
- Timestamp and author: When the version was created and by whom
Once a version is created, its data cannot be changed—any modification creates a new version instead. Restoring a previous version also creates a new version with the same data, preserving your complete version timeline.
Working with draft mode (UI)
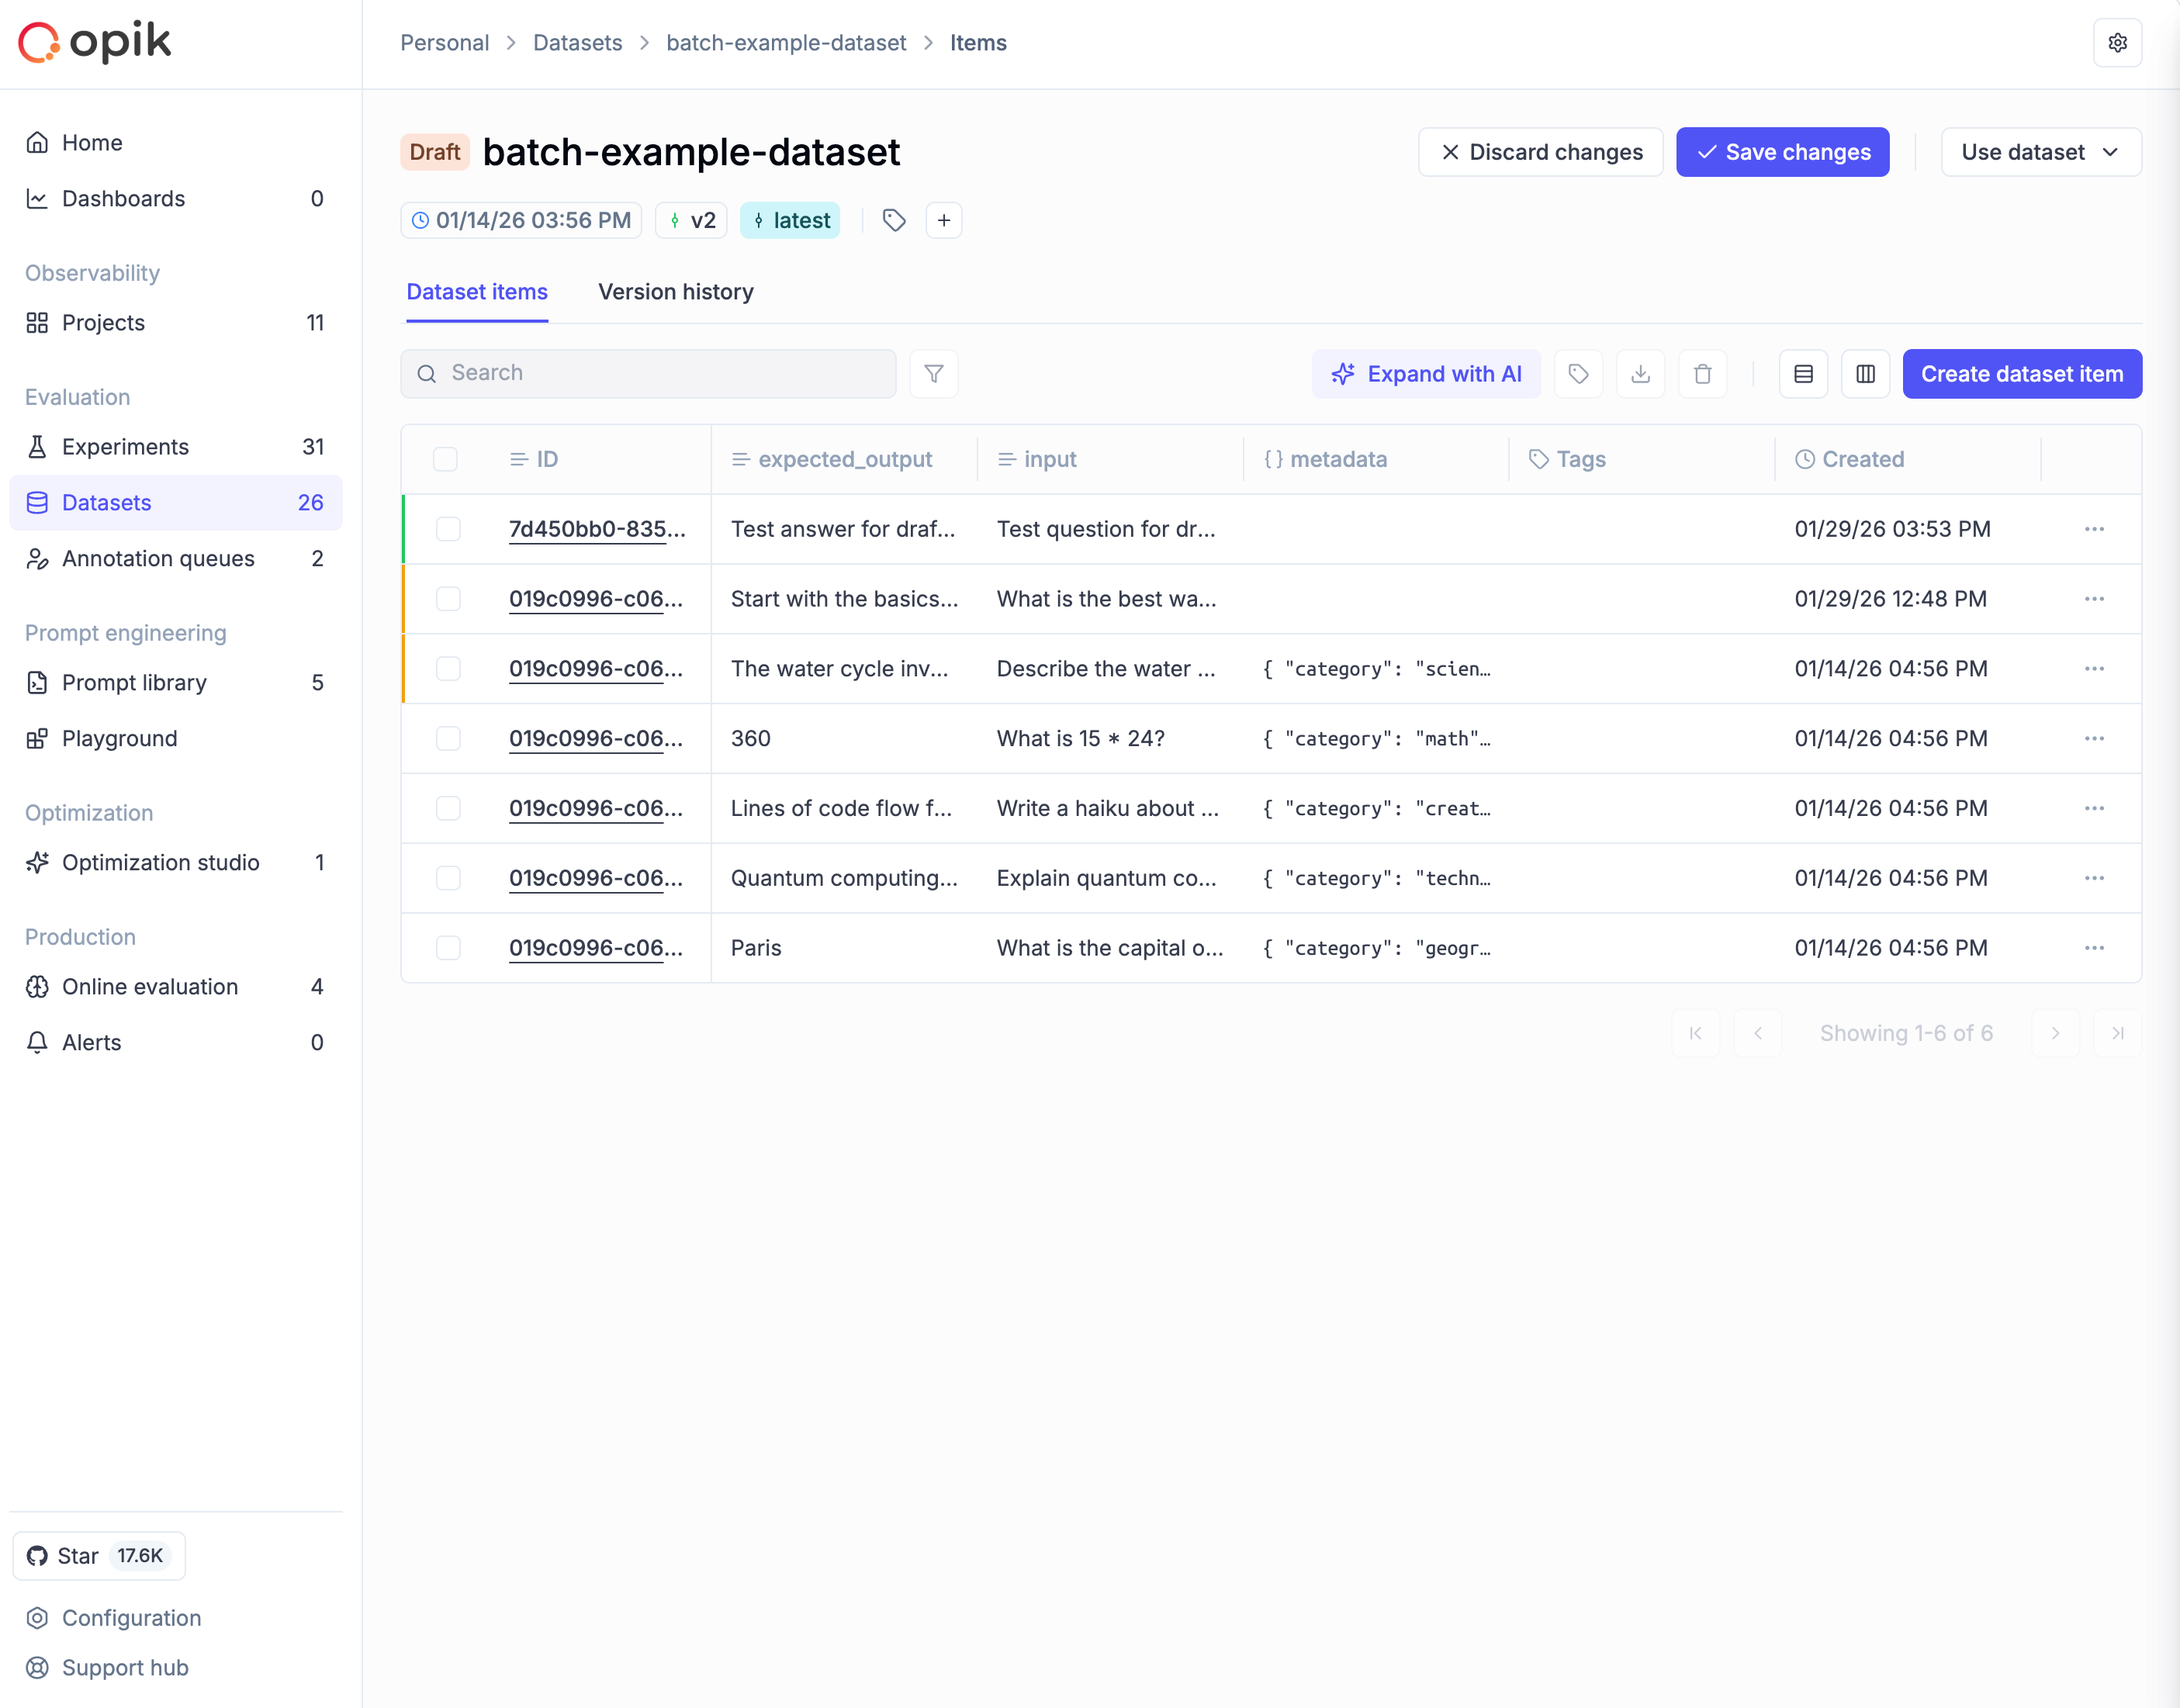
Section titled “Working with draft mode (UI)”When making changes to a dataset in the Opik UI, all modifications go into a draft state first. This gives you a staging area to review changes before committing them as a new version. The draft is visible only to you, and AI-generated samples from "Expand with AI" also go to draft for review.
When a dataset has unsaved draft changes, an orange "Draft" tag appears next to the dataset name, and Save changes / Discard changes buttons appear in the toolbar. Items show colored borders: green for newly added items, amber for modified items.
Saving or discarding changes
Section titled “Saving or discarding changes”To commit your draft as a new version:
- Click Save changes in the toolbar
- Enter a version note describing what changed
- Optionally add tags to categorize this version
- Click Save
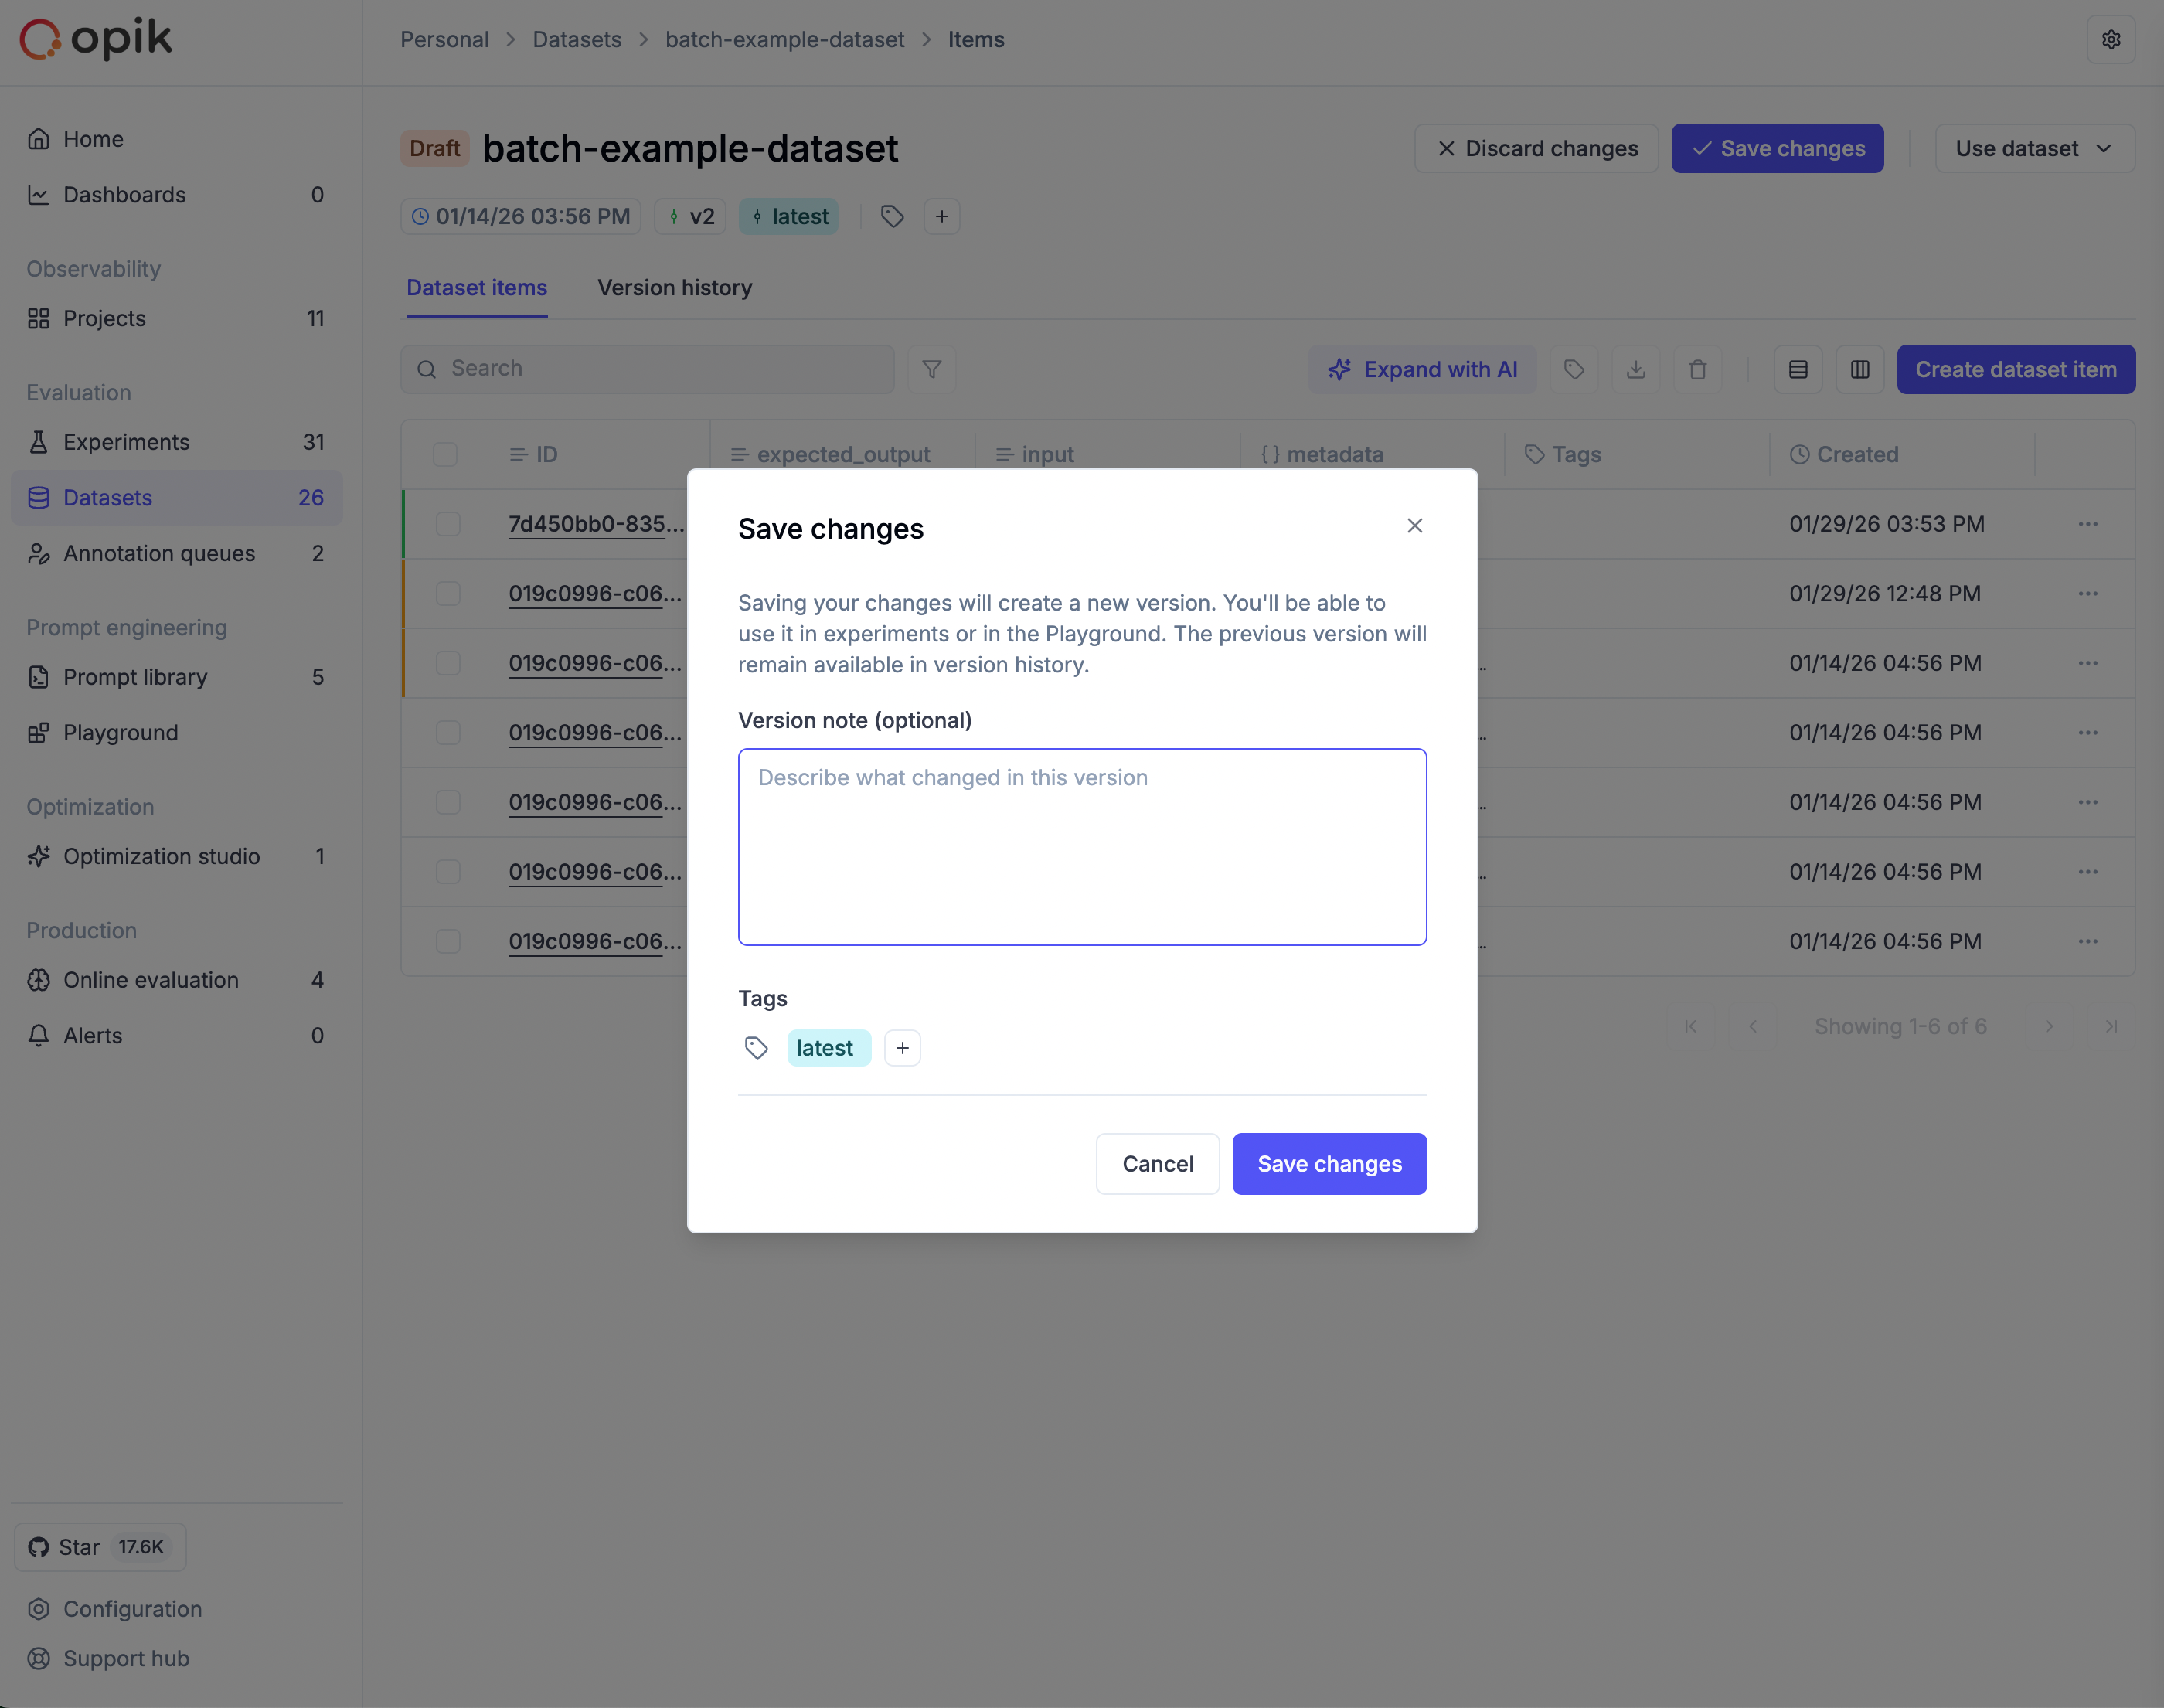
To abandon your draft, click Discard changes and confirm. If you try to navigate away with unsaved changes, Opik displays a warning to prevent accidental loss of work.
Version history
Section titled “Version history”To view the complete timeline of dataset changes, navigate to your dataset and click the Version history tab. The table shows each version's name, change summary (items added/modified/deleted), version note, tags, item count, and creation timestamp.
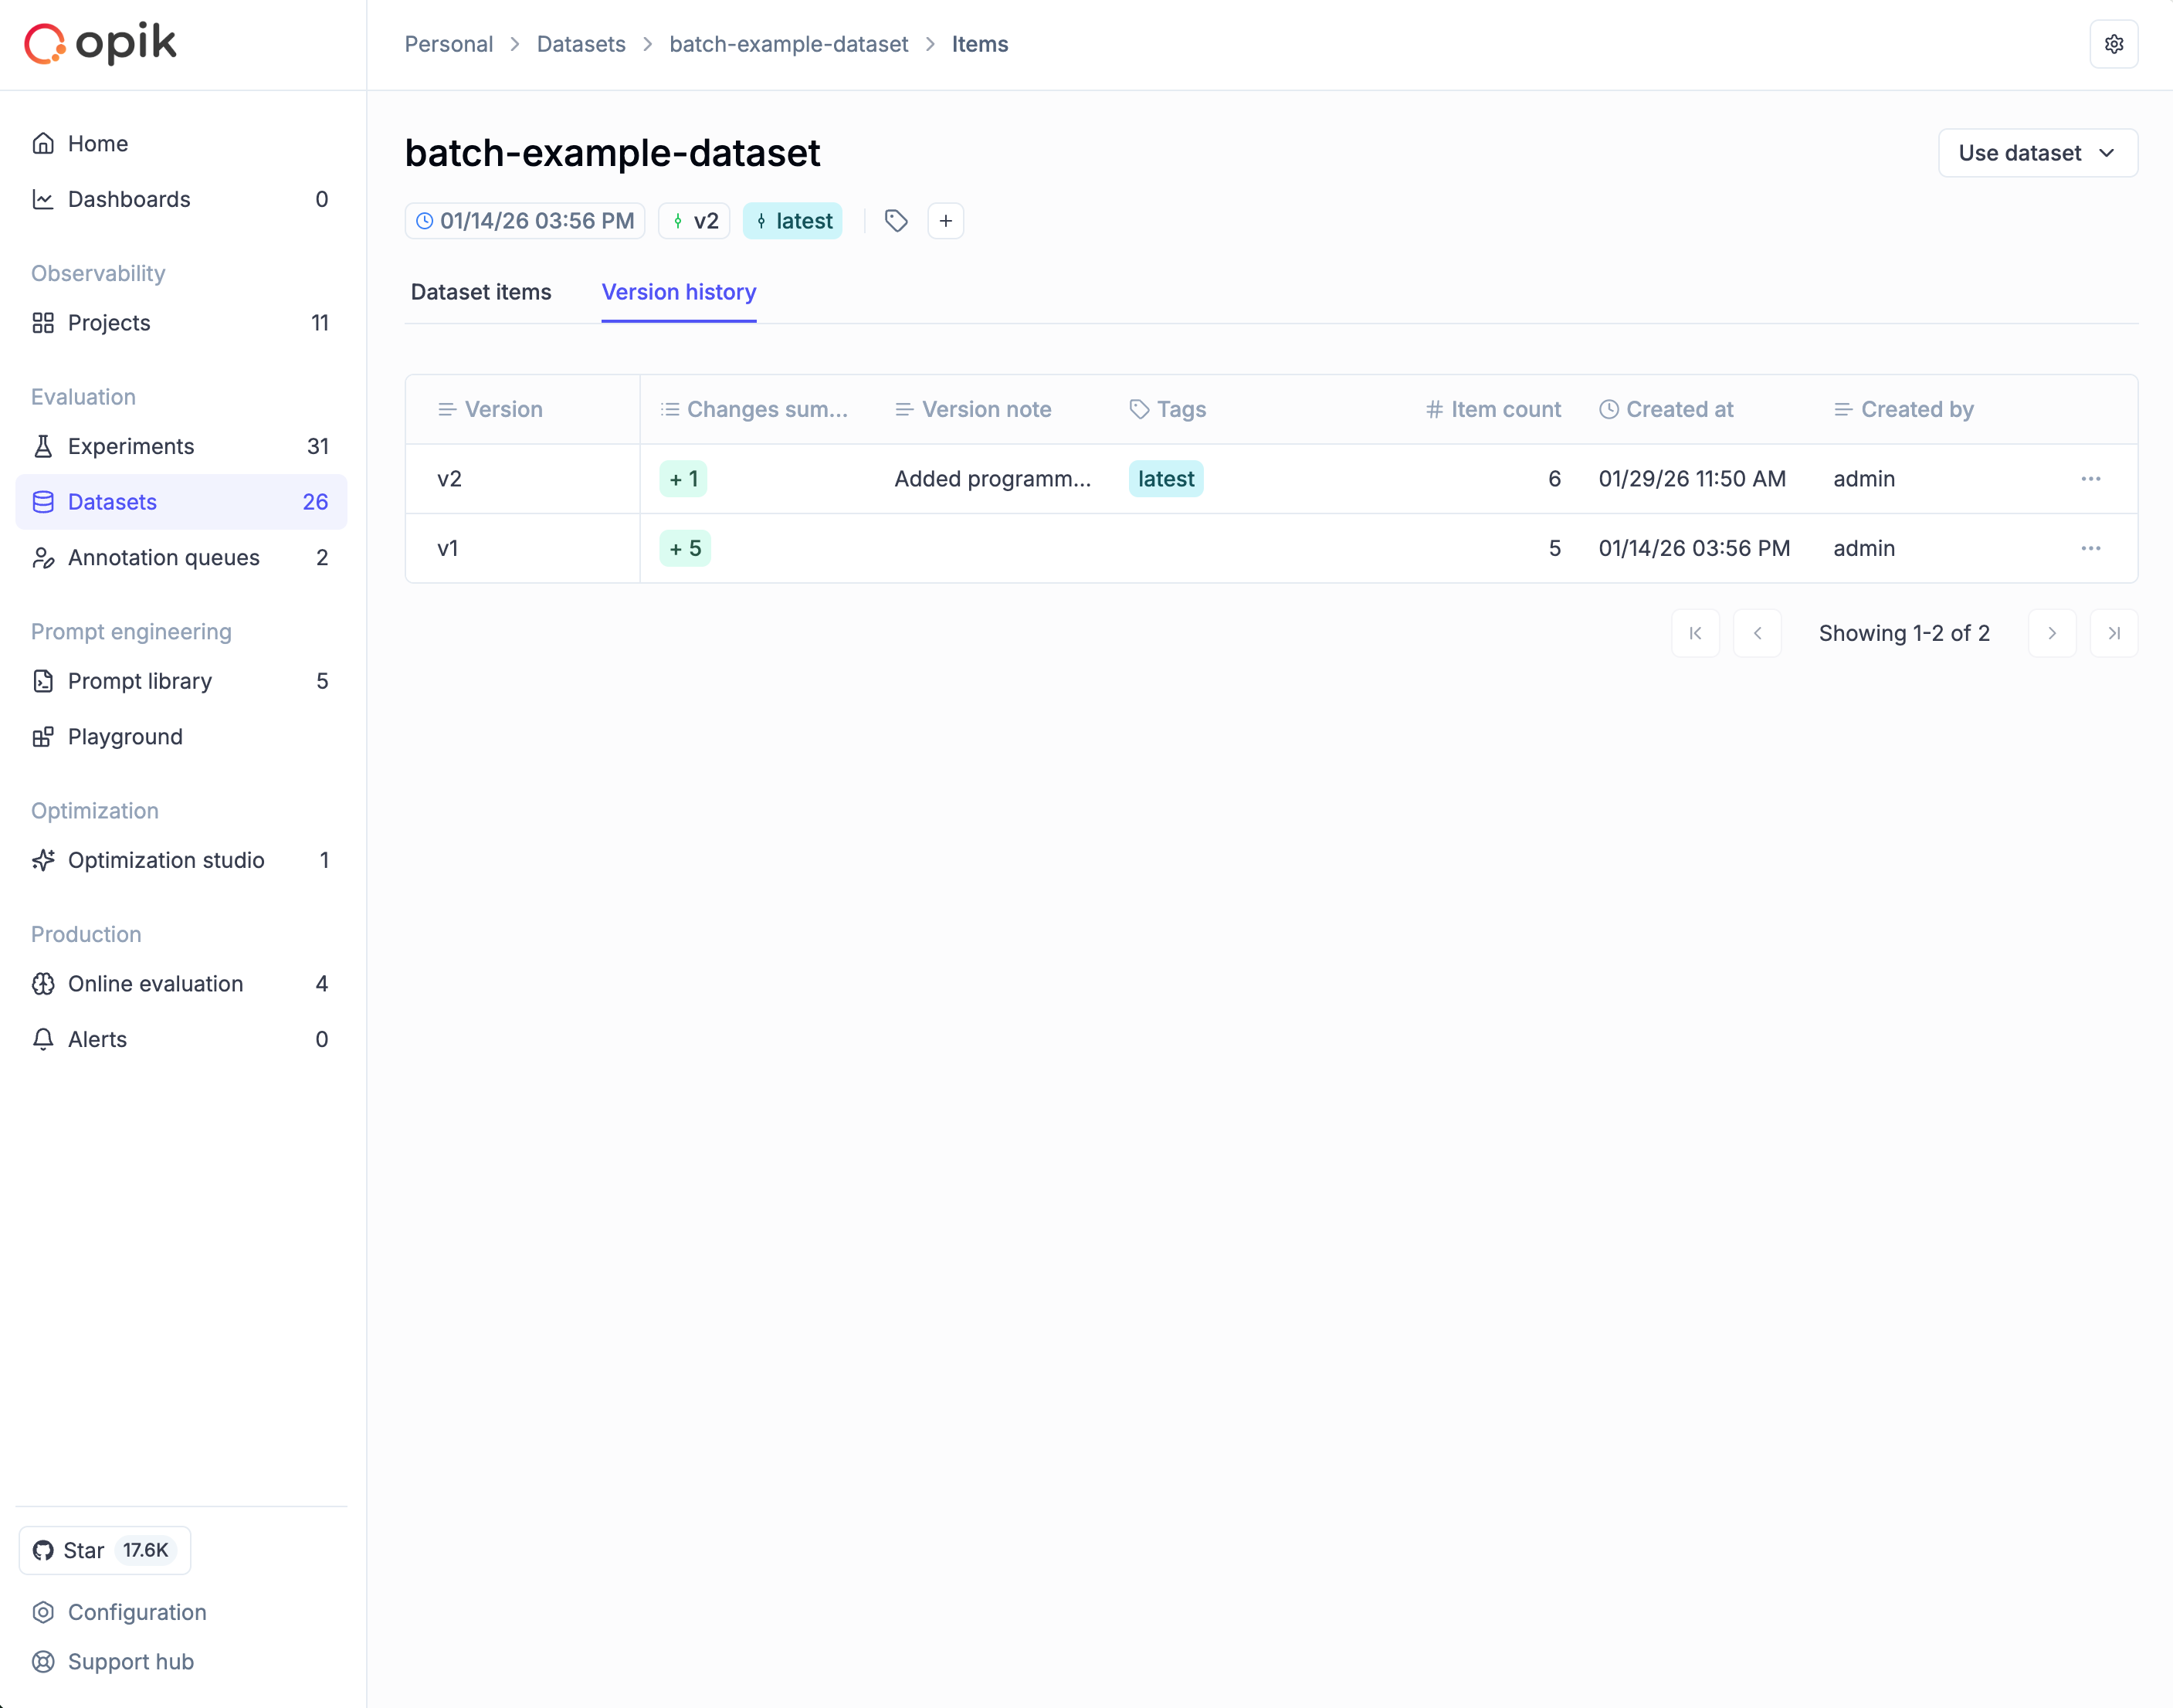
From this view you can:
- View items: Click a version row and select View items to see the exact data at that point in time
- Restore: Click the ⋮ menu and select Restore this version to create a new version with that data
- Edit metadata: Click the ⋮ menu and select Edit to update the version note or tags (the data itself remains immutable)
Managing dataset and version tags from the SDK
Section titled “Managing dataset and version tags from the SDK”The Dataset object exposes get_tags() to read the current tags, but does not yet provide a dedicated setter. To write tags programmatically — for example to drive an env:prod / env:stage promotion workflow — use the REST client exposed on the Opik client.
There are two tag surfaces, depending on what you want to scope the tag to:
- Dataset-level tags apply to the dataset as a whole and persist across versions. Use
update_dataset— this replaces the existing tag list. - Version-level tags apply to a specific dataset version. Use
update_dataset_version— this is additive (it adds to the version's existing tags).
import opik

client = opik.Opik()
dataset = client.get_or_create_dataset(name="my-eval", project_name="my-project")

# Read current dataset-level tags
print(dataset.get_tags())

# Set dataset-level tags (replaces the existing list)
client.rest_client.datasets.update_dataset(
    id=dataset.id,
    name=dataset.name,
    tags=["env:prod"],
)

# Add tags to a specific version (additive)
client.rest_client.datasets.update_dataset_version(
    id=dataset.id,
    version_hash=dataset.version_hash,
    tags_to_add=["env:prod"],
)You can then filter dataset items by these tags via get_items(filter_string=...) using the tags contains operator.
Adding traces to a dataset
Section titled “Adding traces to a dataset”One of the most powerful ways to build evaluation datasets is by converting production traces into dataset items. This allows you to leverage real-world interactions from your LLM application to create test cases for evaluation.
Adding traces via the UI
Section titled “Adding traces via the UI”To add traces to a dataset from the Opik UI:
- Navigate to the traces page
- Select one or more traces you want to add to a dataset
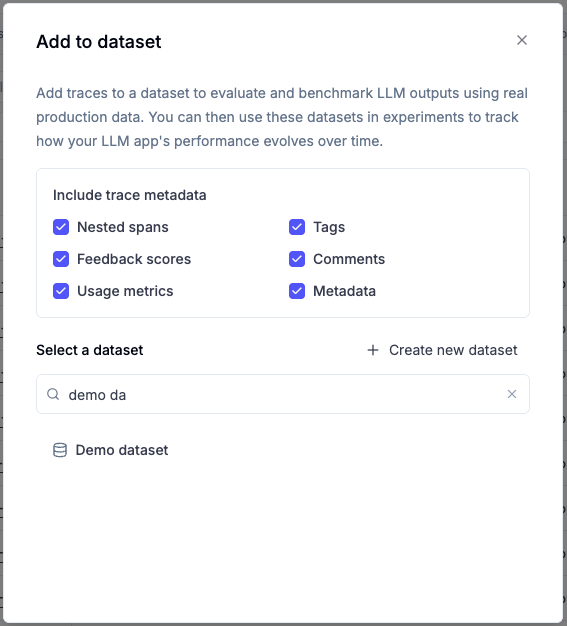
- Click the Add to dataset button in the toolbar
- In the dialog that appears:
- Select an existing dataset or create a new one
- Choose which trace metadata to include:
- Nested spans: Include all child spans within the trace
- Tags: Include trace tags
- Feedback scores: Include any feedback scores attached to the trace
- Comments: Include comments added to the trace
- Usage metrics: Include token usage and cost information
- Metadata: Include custom metadata fields
- Click on the dataset name to add the selected traces
What gets added to the dataset
Section titled “What gets added to the dataset”When you add a trace to a dataset, the following structure is created:
- input: The trace's input data
- expected_output: The trace's output data (stored as
expected_outputfor evaluation purposes) - spans (optional): Array of nested spans with their inputs, outputs, and metadata
- tags (optional): Array of tags associated with the trace
- feedback_scores (optional): Array of feedback scores with name, value, and source
- comments (optional): Array of comments with text and ID
- usage (optional): Token usage and cost information
- metadata (optional): Custom metadata fields
This rich structure allows you to:
- Evaluate complex multi-step workflows by including nested spans
- Filter and analyze based on tags and metadata
- Use existing feedback scores as ground truth for evaluation
- Preserve context through comments and annotations
Creating a dataset using the SDK
Section titled “Creating a dataset using the SDK”You can create a dataset and log items to it using the get_or_create_dataset method:
import { Opik } from "opik";

// Create a dataset
const client = new Opik();
const dataset = await client.getOrCreateDataset("My dataset", "Evaluation dataset", "my-project");from opik import Opik
# Create a dataset
client = Opik()
dataset = client.get_or_create_dataset(name="My dataset", project_name="my-project")If a dataset with the given name already exists, the existing dataset will be returned.
Insert items
Section titled “Insert items”Inserting dictionary items
Section titled “Inserting dictionary items”You can insert items to a dataset using the insert method:
import { Opik } from "opik";
const client = new Opik();
const dataset = await client.getOrCreateDataset("My dataset", "Evaluation dataset", "my-project");

dataset.insert([
  { user_question: "Hello, world!", expected_output: { assistant_answer: "Hello, world!" } },
  { user_question: "What is the capital of France?", expected_output: { assistant_answer: "Paris" } },
]);import opik
# Get or create a dataset
client = opik.Opik()
dataset = client.get_or_create_dataset(name="My dataset", project_name="my-project")
# Add dataset items to it
dataset.insert([
{"user_question": "Hello, world!", "expected_output": {"assistant_answer": "Hello, world!"}},
{"user_question": "What is the capital of France?", "expected_output": {"assistant_answer": "Paris"}},
])Disabling deduplication
Section titled “Disabling deduplication”Deduplication requires the Python SDK to download the dataset's existing items once so it can compare their
content hashes against the items you are inserting. On large datasets that download dominates the insert. If you
already know your items are unique — for example when populating a fresh dataset, or when you generate ids
yourself — pass deduplication=False to skip that work entirely: nothing is downloaded, no hashes are computed,
and every item you pass is sent as-is.
dataset.insert(items, deduplication=False)The flag is available on every Python SDK method that writes items — insert, update, insert_from_json,
insert_from_pandas and read_jsonl_from_file — as well as on the equivalent TestSuite methods. With
deduplication disabled, inserting the same content twice produces two separate dataset items.
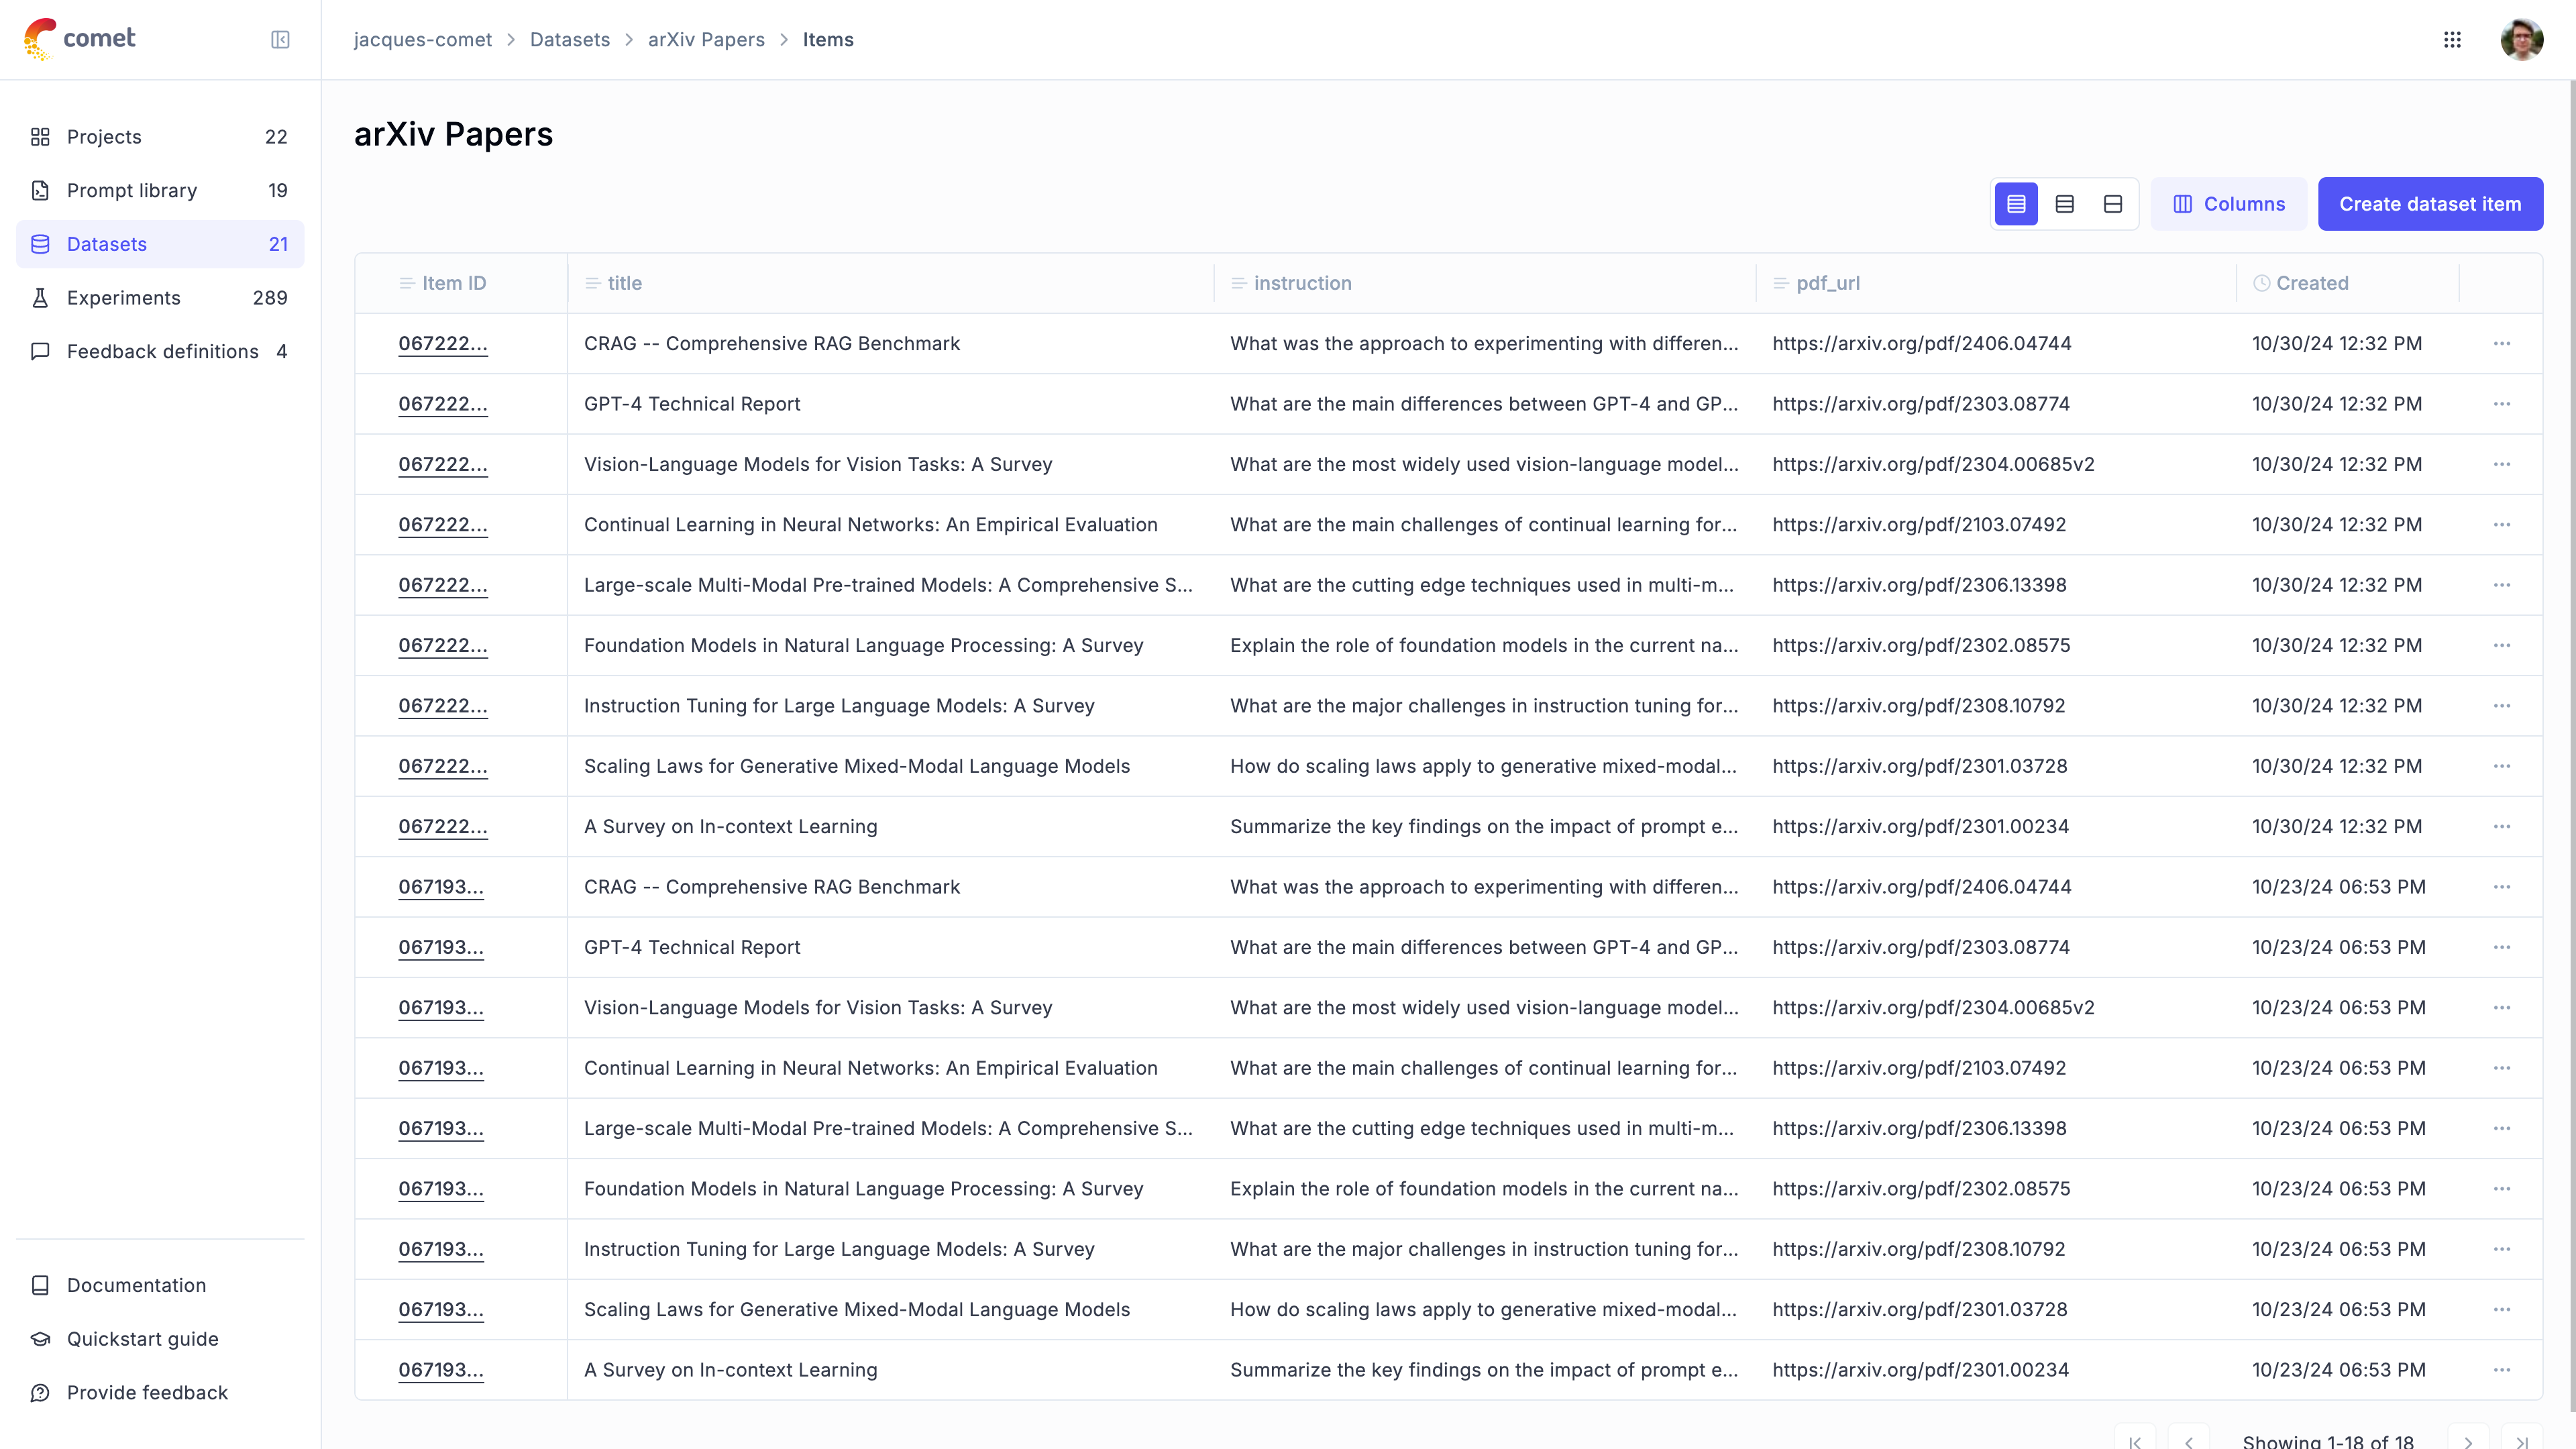
Once the items have been inserted, you can view them in the Opik UI:
Inserting items from a JSONL file
Section titled “Inserting items from a JSONL file”You can also insert items from a JSONL file:
  import opik

  client = opik.Opik()
  dataset = client.get_or_create_dataset(name="My dataset", project_name="my-project")

dataset.read_jsonl_from_file("path/to/file.jsonl")
Inserting items from a Pandas DataFrame
Section titled “Inserting items from a Pandas DataFrame”You can also insert items from a Pandas DataFrame:
import opik

client = opik.Opik()
dataset = client.get_or_create_dataset(name="My dataset", project_name="my-project")

dataset.insert_from_pandas(dataframe=df)

# You can also specify an optional keys_mapping parameter
dataset.insert_from_pandas(dataframe=df, keys_mapping={"Expected output": "expected_output"})
Deleting items
Section titled “Deleting items”You can delete items in a dataset by using the delete method:
import { Opik } from "opik";

// Get or create a dataset
client = new Opik();
dataset = await client.getDataset("My dataset")

await dataset.delete(["123", "456"])

// Or to delete all items
await dataset.clear()from opik import Opik
# Get or create a dataset
client = Opik()
dataset = client.get_dataset(name="My dataset")
dataset.delete(items_ids=["123", "456"])
# Or to delete all items
dataset.clear()Downloading a dataset from Opik
Section titled “Downloading a dataset from Opik”You can download a dataset from Opik using the get_dataset method:
import { Opik } from "opik";

const client = new Opik();
const dataset = await client.getDataset("My dataset");

const items = await dataset.getItems();
console.log(items);from opik import Opik
client = Opik()
dataset = client.get_dataset(name="My dataset")
# Get items as list of DatasetItem objects
items = dataset.get_items()
# Convert to a Pandas DataFrame
dataset.to_pandas()
# Convert to a JSON array
dataset.to_json()Downloading large datasets faster
Section titled “Downloading large datasets faster”Dataset items are fetched a page at a time, and those pages are downloaded concurrently. The default is
8 threads; pass num_threads to read with more or fewer (see Tuning SDK throughput):
from opik import Opik

client = Opik()
dataset = client.get_dataset(name="My dataset")

# The whole dataset as one list, downloaded over 16 threads
items = dataset.get_items(num_threads=16)
The thread count never changes the result, only how quickly it arrives.
get_items() returns the whole dataset as a single list, so the call does not return until every
item has been downloaded and the full result is held in memory. stream_items() reads the same
items in chunks instead, yielding each chunk as soon as it arrives. Use it when you want to start
processing before the download finishes, or when the dataset is too large to hold in memory all at
once:
from opik import Opik

client = Opik()
dataset = client.get_dataset(name="My dataset")

# One chunk at a time, instead of the whole dataset at once
for chunk in dataset.stream_items(chunk_size=5000):
    process(chunk)  # a list of dicts, exactly as get_items() returns them
Chunks arrive in dataset order; only the last one may be shorter than chunk_size. Both methods
accept the same filter_string, and nb_samples to read only the first N items:
for chunk in dataset.stream_items(
    filter_string='data.category = "geography"',
    nb_samples=10_000,
):
    process(chunk)
nb_samples must be a positive integer — omit it or pass None to read everything. Passing 0
or a negative value raises ValueError rather than being treated as a limit.
Tuning SDK throughput
Section titled “Tuning SDK throughput”The Python SDK moves dataset and experiment items on a pool of worker threads. Every one of these
paths defaults to 8 threads, which is what we benchmark against and what we recommend for
customer-scale datasets — you should not need to pass num_threads at all:
| Operation | Call | Default |
|---|---|---|
| Dataset read | dataset.get_items(), dataset.stream_items() |
8 |
| Dataset write | dataset.insert() |
8 |
| Experiment write | experiment.batch_upload_items() |
8 |
Each of those takes a num_threads argument if you do want to change it:
items = dataset.get_items(num_threads=4)       # read more gently
dataset.insert(items, num_threads=16)          # more concurrency, if the client has CPU headroom
experiment.batch_upload_items(records, num_threads=1)  # upload sequentially
Raise it when the client is idle waiting on the network — a big upload over a high-latency link is the usual case. Do not expect much: on a 119,903-item upload we measured 16 threads running slightly slower than 8, because the SDK saturates a CPU core serializing and compressing payloads long before thread count becomes the limit. Past 8, extra workers mostly add scheduling overhead.
Lower it when you are sharing a rate limit with other jobs, when the client machine is small, or
when individual items are large enough that memory matters. On the dataset paths, num_threads
bounds memory as well as concurrency: a read holds up to 2 * num_threads chunks and an upload up
to 2 * num_threads request bodies, whatever the dataset's size. experiment.batch_upload_items()
does not work that way — it builds every batch up front and queues them all, so its peak memory
tracks the total number of items and lowering num_threads will not contain it. Split the records
across calls if an experiment upload is too large to hold.
num_threads=1 makes the operation fully sequential, which is the only setting that guarantees
batches arrive in order.
Filtering datasets programmatically
Section titled “Filtering datasets programmatically”You can filter dataset items using the filter_string parameter on the get_items() method or when
running evaluations with evaluate_prompt(). This allows you to work with specific subsets of your data.
Basic filtering
Section titled “Basic filtering”from opik import Opik
client = Opik()
dataset = client.get_dataset(name="my_dataset")
# Get filtered items
failed_items = dataset.get_items(filter_string='tags contains "failed"')
Filter syntax
Section titled “Filter syntax”The filter string uses Opik Query Language (OQL) syntax. Supported columns include:
| Column | Type | Description |
|---|---|---|
id |
String | Unique identifier for the dataset item |
source |
String | Source of the dataset item |
trace_id |
String | Associated trace ID |
span_id |
String | Associated span ID |
data |
Dictionary | Use dot notation for nested fields (e.g., data.category) |
tags |
List | Use "contains" operator (e.g., tags contains "test") |
created_at |
DateTime | ISO 8601 format (e.g., created_at >= "2024-01-01T00:00:00Z") |
last_updated_at |
DateTime | ISO 8601 format |
created_by |
String | User who created the item |
last_updated_by |
String | User who last updated the item |
Filter examples
Section titled “Filter examples”from opik import Opik
client = Opik()
dataset = client.get_dataset(name="my_dataset")
# Filter by tag
failed_items = dataset.get_items(filter_string='tags contains "failed"')
# Filter by data field
finance_items = dataset.get_items(filter_string='data.category = "finance"')
# Filter by date
recent_items = dataset.get_items(
filter_string='created_at >= "2024-06-01T00:00:00Z"'
)
# Multiple conditions
filtered_items = dataset.get_items(
filter_string='tags contains "production" AND data.difficulty = "hard"'
)Running experiments with dataset versions
Section titled “Running experiments with dataset versions”When you run an experiment, Opik automatically links it to the specific dataset version that was used. This ensures complete reproducibility—you can always know exactly which data was used for any experiment.
Automatic version association
Section titled “Automatic version association”Every experiment records which dataset version it used:
- When running from the UI or SDK without specifying a version, the
latestversion is used - The experiment results page shows the associated dataset version
- You can click the version to see the exact data that was evaluated
This association is permanent. Even if you later modify the dataset, your experiment results remain linked to the original version used.
Selecting a specific version in Playground
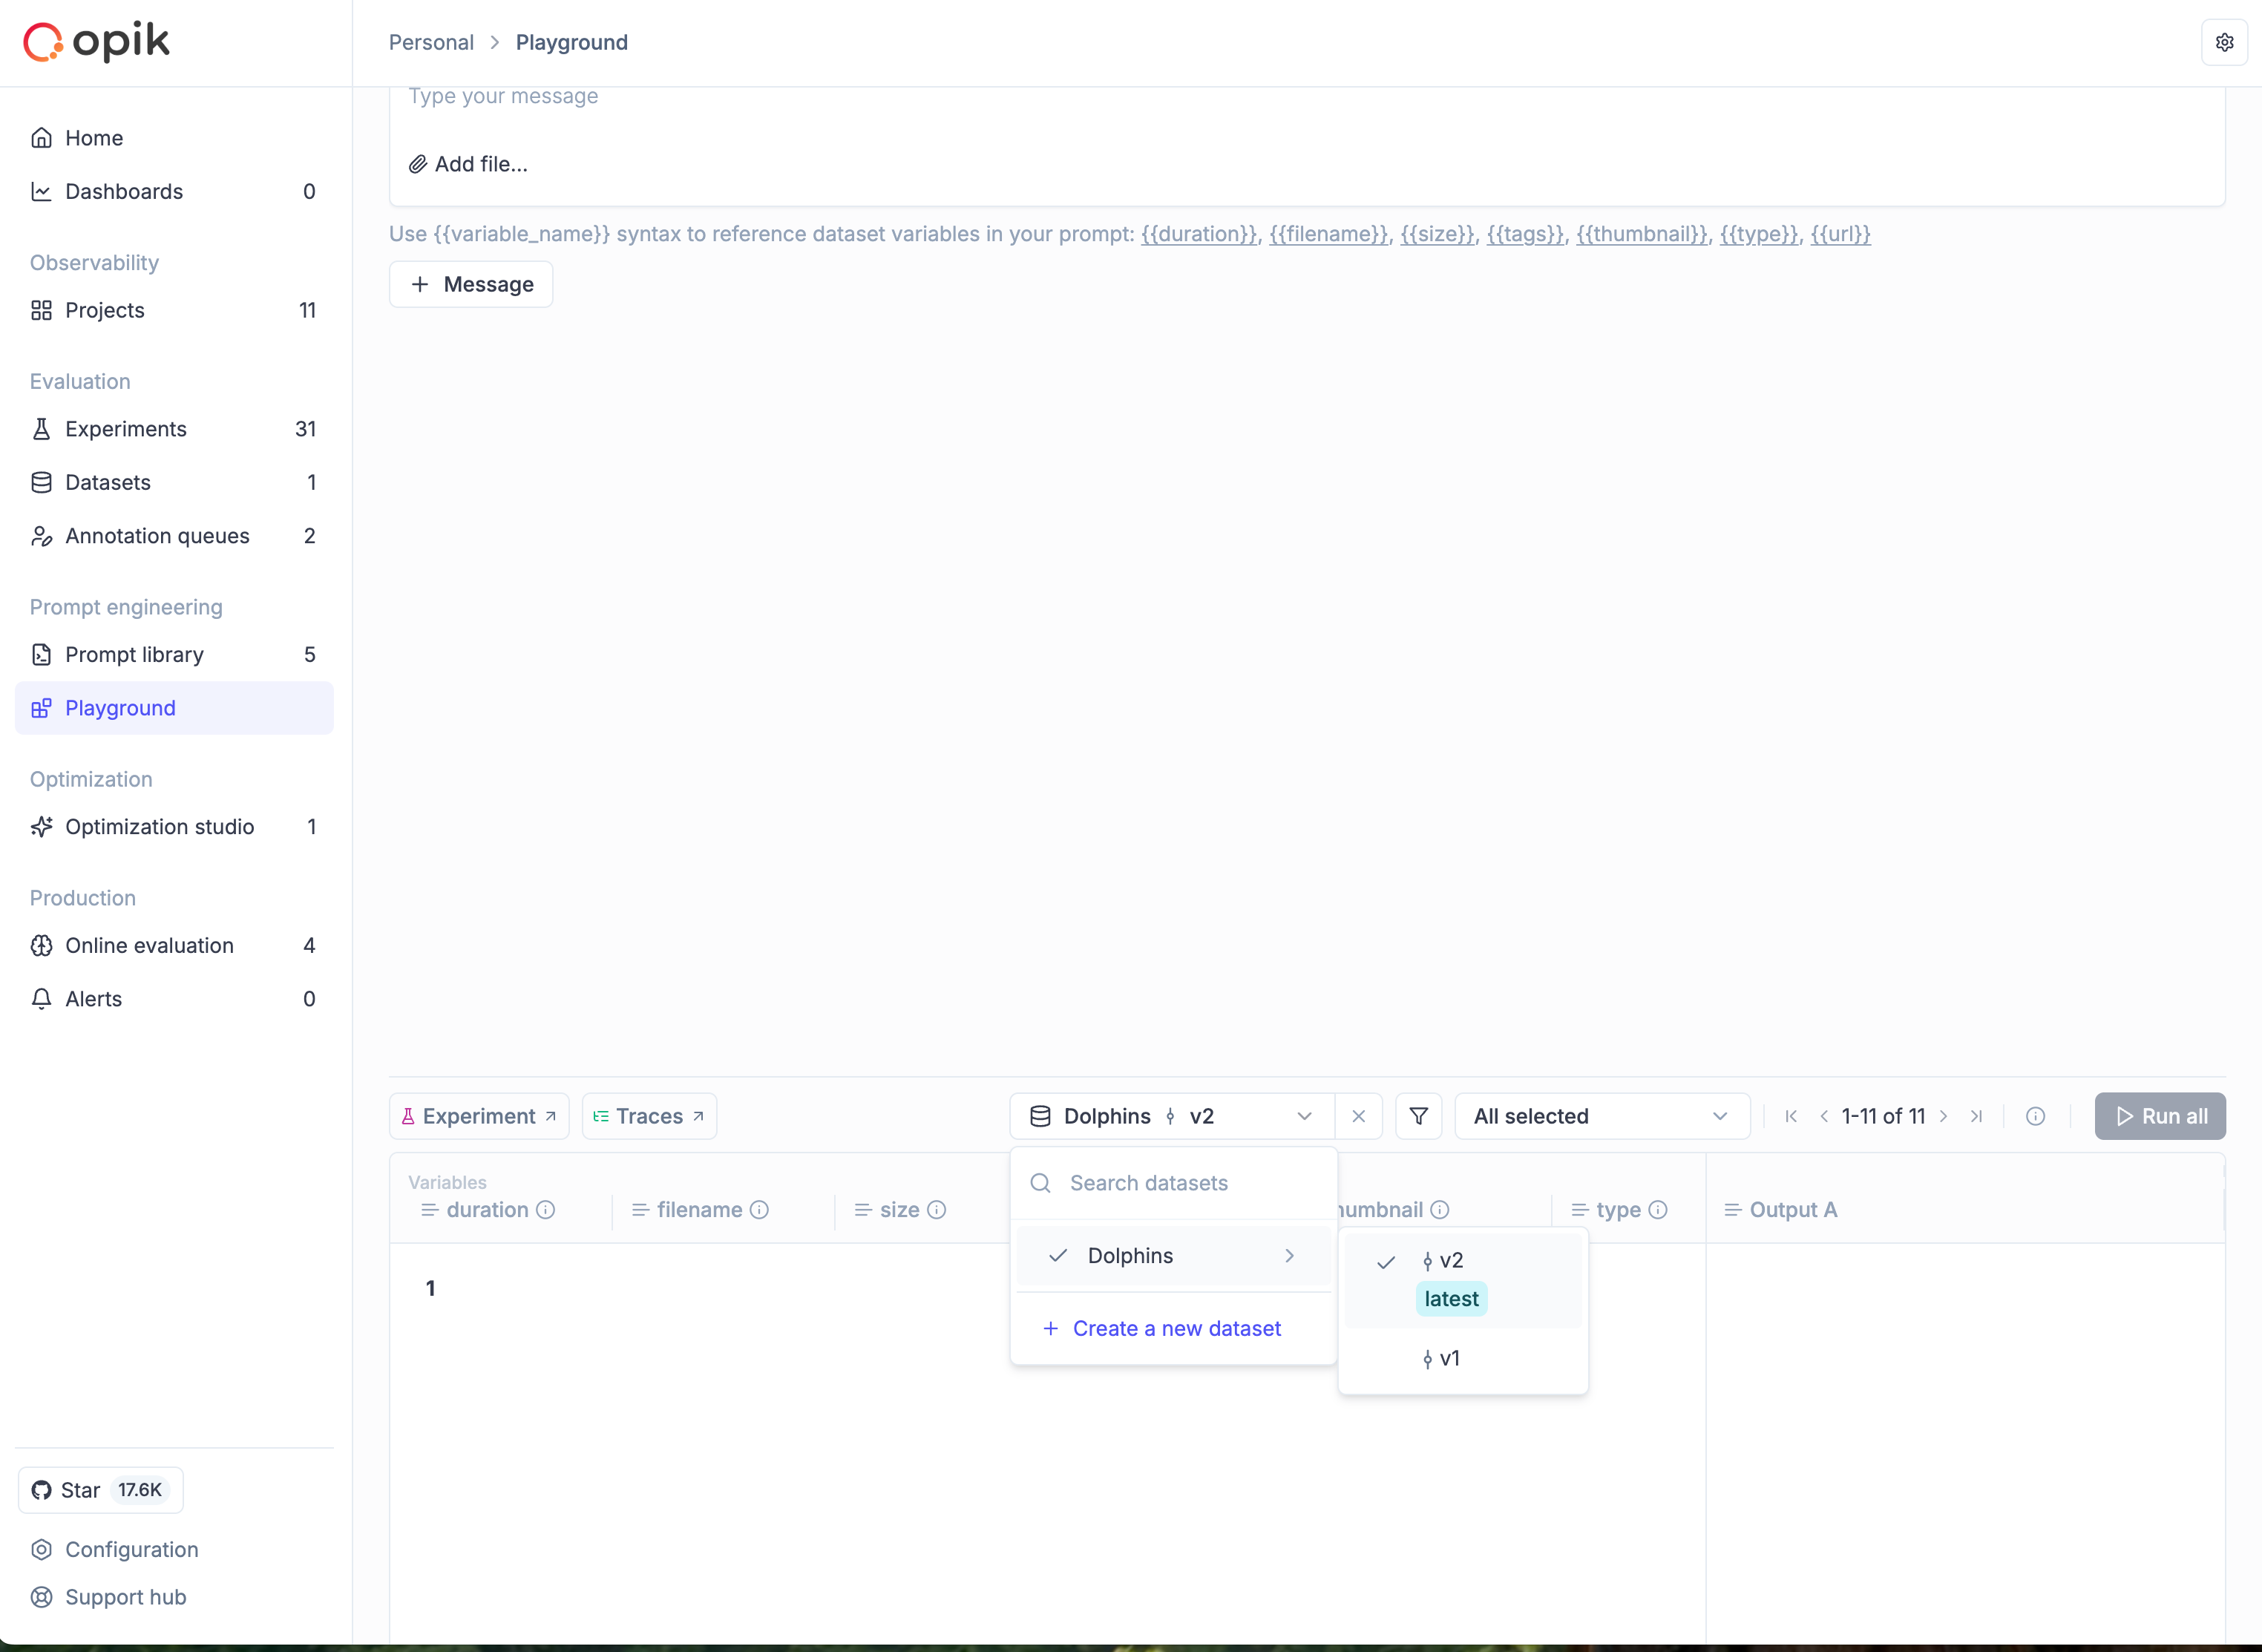
Section titled “Selecting a specific version in Playground”When running experiments from the Playground:
- Open the Playground and configure your prompt
- In the dataset selector, choose your dataset
- A nested dropdown appears showing available versions
- Select the specific version you want to use, or choose
latestfor the most recent
Selecting a specific version in the SDK
Section titled “Selecting a specific version in the SDK”When running experiments programmatically, you can specify which dataset version to use by passing a DatasetVersion object to evaluate():
from opik import Opik
from opik.evaluation import evaluate

client = Opik()
dataset = client.get_dataset(name="My dataset")

# Run experiment on the latest version (default behavior)
result = evaluate(
    experiment_name="baseline-experiment",
    dataset=dataset,
    task=my_task_function,
    scoring_metrics=[my_metric],
    project_name="my-project",
)

# Run experiment on a specific version
v1_view = dataset.get_version_view("v1")
result = evaluate(
    experiment_name="v1-experiment",
    dataset=v1_view,  # Pass the DatasetVersion object
    task=my_task_function,
    scoring_metrics=[my_metric],
    project_name="my-project",
)import { Opik, evaluate } from "opik";
const client = new Opik();
const dataset = await client.getDataset("My dataset");
// Run experiment on the latest version (default)
const result = await evaluate({
experimentName: "baseline-experiment",
dataset: dataset,
task: myTaskFunction,
scoringMetrics: [myMetric],
projectName: "my-project",
});
// Run experiment on a specific version
const v2 = await dataset.getVersionView("v2");
const pinnedResult = await evaluate({
experimentName: "pinned-experiment",
dataset: v2,
task: myTaskFunction,
scoringMetrics: [myMetric],
projectName: "my-project",
});Working with dataset versions programmatically
Section titled “Working with dataset versions programmatically”The SDK provides methods for inspecting and working with dataset versions:
from opik import Opik

client = Opik()
dataset = client.get_dataset(name="My dataset")

# Get the current (latest) version name
current_version = dataset.get_current_version_name()
print(f"Current version: {current_version}")  # e.g., "v3"

# Get detailed version info (returns DatasetVersionPublic)
version_info = dataset.get_version_info()
print(f"Version ID: {version_info.id}")
print(f"Version name: {version_info.version_name}")
print(f"Items total: {version_info.items_total}")
print(f"Created at: {version_info.created_at}")

# Get a read-only view of a specific version
v1_view = dataset.get_version_view("v1")

# Access version metadata
print(f"Version: {v1_view.version_name}")
print(f"Items in v1: {v1_view.items_total}")
print(f"Items added: {v1_view.items_added}")
print(f"Items modified: {v1_view.items_modified}")
print(f"Items deleted: {v1_view.items_deleted}")

# Get items from a specific version
v1_items = v1_view.get_items()

# Export version data
v1_df = v1_view.to_pandas()
v1_json = v1_view.to_json()import { Opik } from "opik";
const client = new Opik();
const dataset = await client.getDataset("My dataset");
// Get the current (latest) version name
const currentVersion = await dataset.getCurrentVersionName();
console.log(`Current version: ${currentVersion}`); // e.g., "v3"
// Get detailed version info (returns DatasetVersionPublic)
const versionInfo = await dataset.getVersionInfo();
console.log(`Version ID: ${versionInfo?.id}`);
console.log(`Version name: ${versionInfo?.versionName}`);
console.log(`Items total: ${versionInfo?.itemsTotal}`);
console.log(`Created at: ${versionInfo?.createdAt}`);
// Get a read-only view of a specific version
const v1View = await dataset.getVersionView("v1");
// Access version metadata
console.log(`Version: ${v1View.versionName}`);
console.log(`Items in v1: ${v1View.itemsTotal}`);
console.log(`Items added: ${v1View.itemsAdded}`);
console.log(`Items modified: ${v1View.itemsModified}`);
console.log(`Items deleted: ${v1View.itemsDeleted}`);
// Get items from a specific version
const v1Items = await v1View.getItems();
// Export version data as JSON
const v1Json = await v1View.toJson();Expanding a dataset with AI
Section titled “Expanding a dataset with AI”Dataset expansion allows you to use AI to generate additional synthetic samples based on your existing dataset. This is particularly useful when you have a small dataset and want to create more diverse test cases to improve your evaluation coverage.
The AI analyzes the patterns in your existing data and generates new samples that follow similar structures while introducing variations. This helps you:
- Increase dataset size for more comprehensive evaluation
- Create edge cases and variations you might not have considered
- Improve model robustness by testing against diverse inputs
- Scale your evaluation without manual data creation
How to expand a dataset
Section titled “How to expand a dataset”To expand a dataset with AI:
- Navigate to your dataset in the Opik UI (Evaluation > Datasets > [Your Dataset])
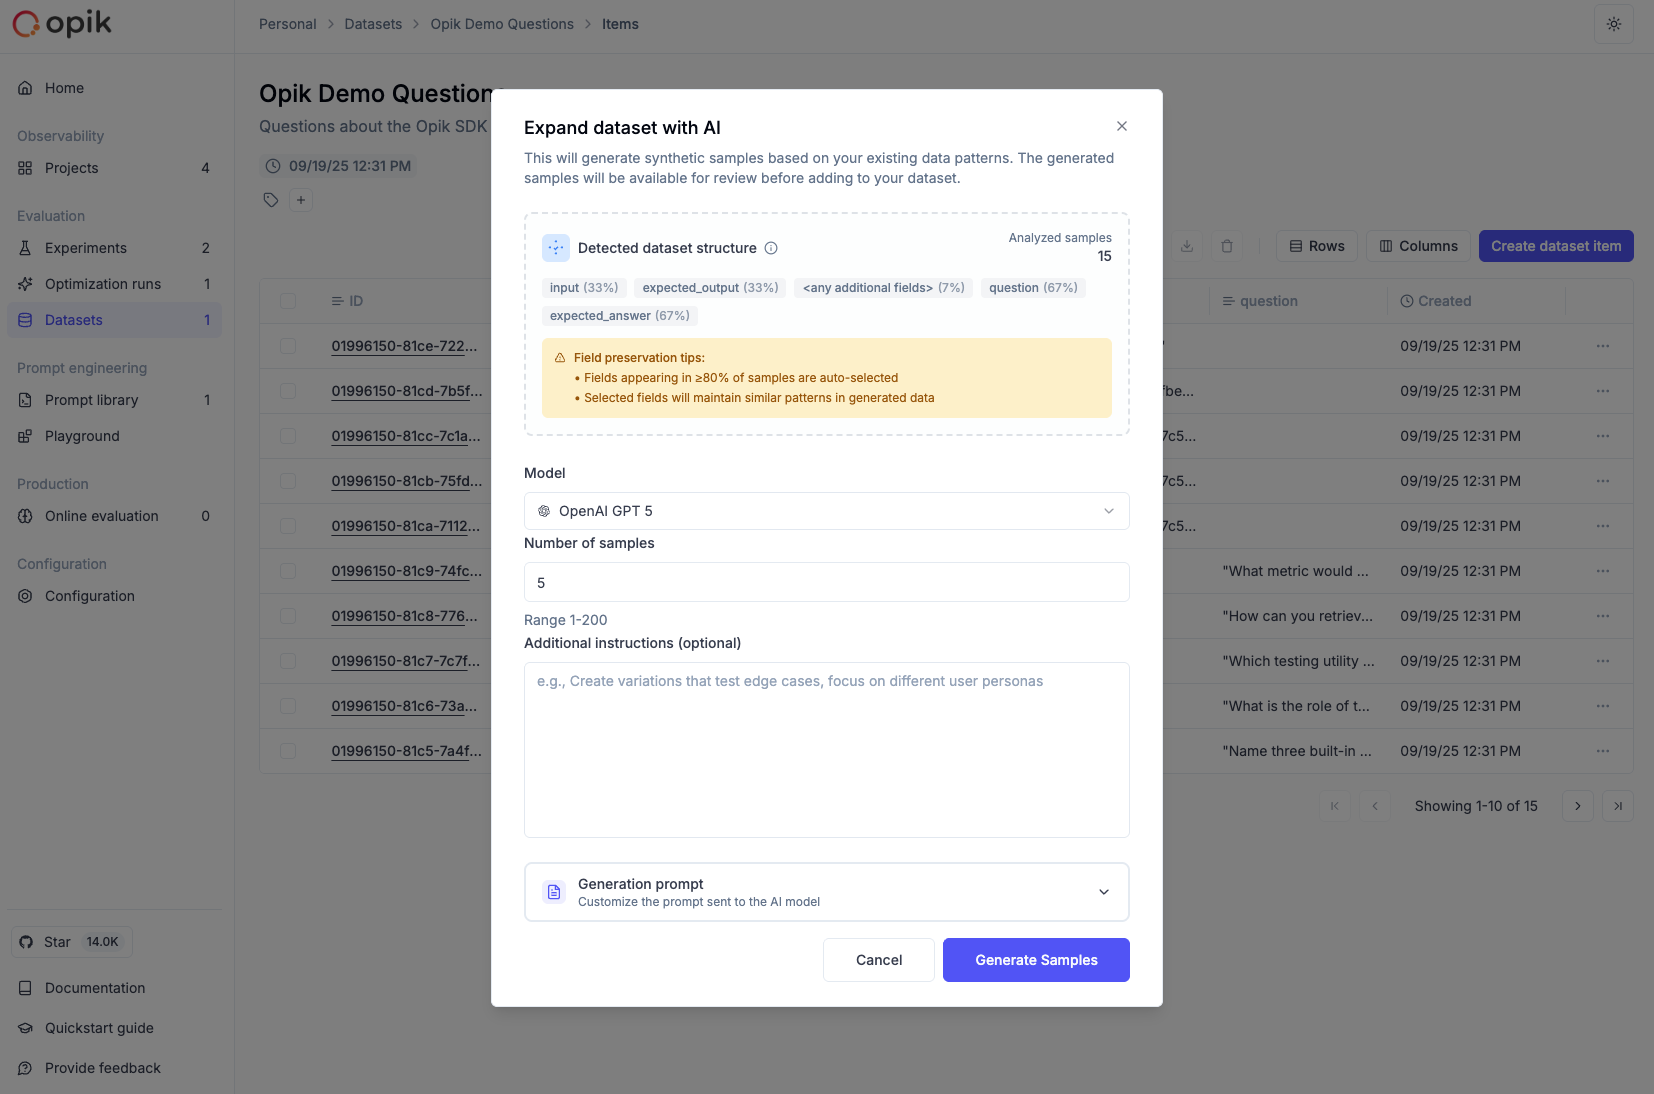
- Click the "Expand with AI" button in the dataset view
- Configure the expansion settings:
- Model: Choose the LLM model to use for generation (supports GPT-4, GPT-5, Claude, and other models)
- Sample Count: Specify how many new samples to generate (1-100)
- Preserve Fields: Select which fields from your original data to keep unchanged
- Variation Instructions: Provide specific guidance on how to vary the data (e.g., "Create variations that test edge cases" or "Generate examples with different complexity levels")
- Custom Prompt: Optionally provide a custom prompt template instead of the auto-generated one
- Start the expansion - The AI will analyze your data and generate new samples
- Review the results - Generated samples are added to your draft. You can review, edit, or remove them before saving to create a new version
Configuration options
Section titled “Configuration options”Sample Count: Start with a smaller number (10-20) to review the quality before generating larger batches.
Preserve Fields: Use this to maintain consistency in certain fields while allowing variation in others. For example, preserve the category field while varying the input and expected_output.
Variation Instructions: Provide specific guidance such as:
- "Create variations with different difficulty levels"
- "Generate edge cases and error scenarios"
- "Add examples with different input formats"
- "Include multilingual variations"
Best practices
Section titled “Best practices”- Start small: Generate 10-20 samples first to evaluate quality before scaling up
- Review generated content: Always review AI-generated samples for accuracy and relevance
- Use variation instructions: Provide clear guidance on the type of variations you want
- Preserve key fields: Use field preservation to maintain important categorizations or metadata
- Iterate and refine: Use the custom prompt option to fine-tune generation for your specific needs
Managing dataset item tags
Section titled “Managing dataset item tags”Tags are a powerful way to organize, categorize, and filter your dataset items. You can use tags to:
- Categorize test cases by type, difficulty, or domain (e.g.,
edge-case,production,multilingual) - Track data sources where items originated from (e.g.,
user-feedback,synthetic,real-world) - Mark review status during dataset curation (e.g.,
needs-review,validated,archived) - Filter for evaluation to run experiments on specific subsets of your data
- Organize workflows by marking items for different stages or teams
Each dataset item can have multiple tags.
Adding tags to dataset items
Section titled “Adding tags to dataset items”Adding tags to individual items
Section titled “Adding tags to individual items”To add tags to a single dataset item:
- Navigate to your dataset in the Opik UI (Evaluation > Datasets > [Your Dataset])
- Click on any dataset item to open the details panel
- In the Tags section, click the "+" button
- Type the tag name and press Enter
- The tag will be immediately added and saved
You can remove tags by clicking the "×" icon next to any tag in the details panel.
Adding tags to multiple items (batch operation)
Section titled “Adding tags to multiple items (batch operation)”To add the same tag to multiple dataset items at once:
- Navigate to your dataset in the Opik UI
- Select multiple items by clicking the checkboxes next to each item
- Click the "Add tags" button in the toolbar (visible when items are selected)
- Enter the tag name in the dialog that appears
- Click "Add tag" to apply the tag to all selected items
This is particularly useful when you want to categorize a group of related test cases or mark items from the same data source.
Filtering dataset items by tags
Section titled “Filtering dataset items by tags”Once you've tagged your dataset items, you can filter them to work with specific subsets:
- Navigate to your dataset in the Opik UI
- Click the "Filters" button next to the search bar
- Select "Tags" from the Column dropdown
- Choose "contains" as the operator
- Enter the tag name you want to filter by
- Close the dialog to apply the filter
The dataset items table will update to show only items matching your filter criteria. You can:
- View filtered items to focus on specific categories
- Run experiments on filtered subsets by using the filtered view
- Export filtered data for specific test case groups
- Combine with other filters to create complex queries
The filter is saved in the URL, so you can bookmark or share specific filtered views of your dataset.
Bulk operations
Section titled “Bulk operations”Opik supports bulk operations for efficiently managing large datasets. These operations help you work with many items at once without tedious individual selections.
Select all functionality
Section titled “Select all functionality”When working with datasets that span multiple pages:
- Select items on the current page using the checkbox in the table header
- A banner appears offering to "Select all items" across all pages
- Click to select all items matching your current filter criteria
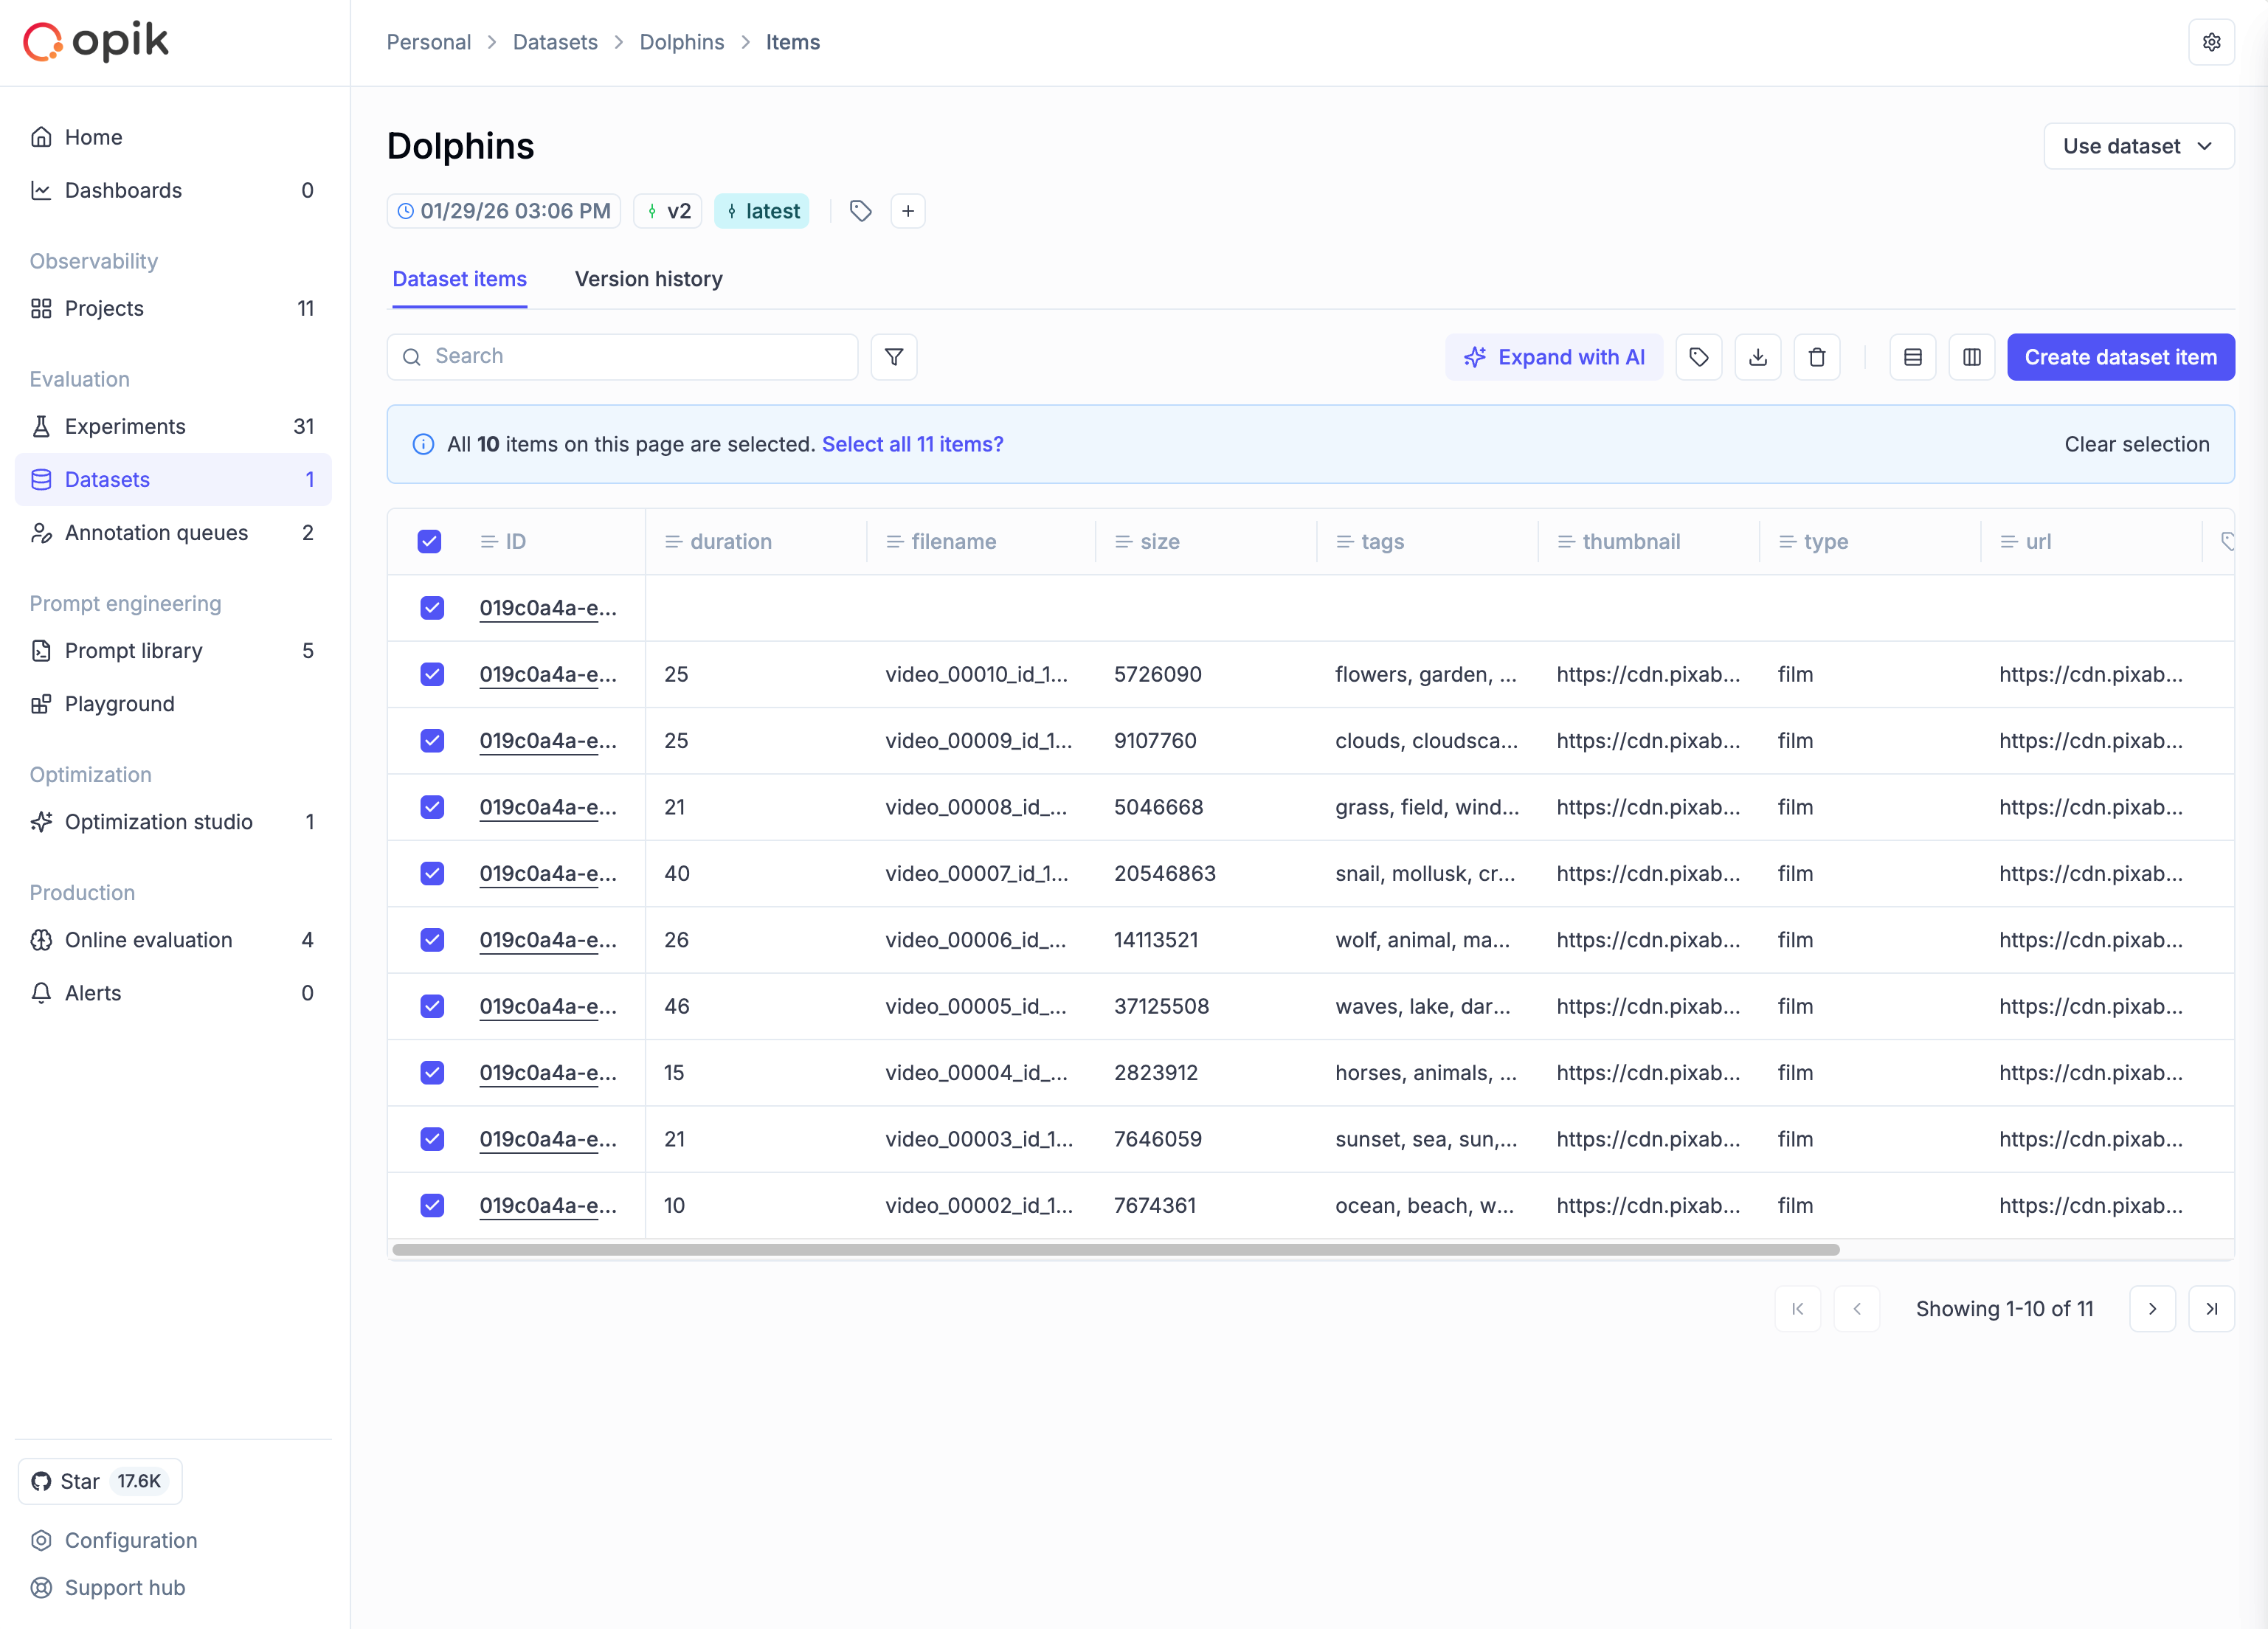
This works with filtered views too—if you have a filter applied, "Select all" only selects items matching that filter.
Available bulk operations
Section titled “Available bulk operations”Once you have items selected, the toolbar shows available operations:
- Add tags: Apply one or more tags to all selected items
- Delete: Remove selected items (creates a new version with items removed)
- Export: Download selected items as CSV or JSON
Processing indicators
Section titled “Processing indicators”For large bulk operations:
- A loading indicator shows "Your dataset is still processing..."
- The operation runs in the background—you can continue browsing
- A success message appears when processing completes