
Export data
Opik gives you several ways to export the data you've logged — pick the one that fits your workflow.
The Python and TypeScript SDKs let you search and export traces, spans, and threads programmatically.
Traces
Section titled “Traces”import opik
client = opik.Opik()
# Export all traces
traces = client.search_traces(project_name="Default project", max_results=1000000)
# Export filtered traces
traces = client.search_traces(
project_name="Default project",
filter_string='input contains "Opik"'
)
# Convert to dict if needed
traces = [trace.dict() for trace in traces]import { Opik } from "opik";
const client = new Opik();
// Export all traces
const traces = await client.searchTraces({
projectName: "Default project",
maxResults: 1000000,
});
// Export filtered traces
const filtered = await client.searchTraces({
projectName: "Default project",
filterString: 'input contains "Opik"',
});import opik
client = opik.Opik()
# Export spans by trace ID
spans = client.search_spans(
project_name="Default project",
trace_id="067092dc-e639-73ff-8000-e1c40172450f"
)
# Export filtered spans
spans = client.search_spans(
project_name="Default project",
filter_string='input contains "Opik"'
)Threads
Section titled “Threads”import opik
client = opik.Opik()
# Export all threads
threads = client.search_threads(project_name="Default project", max_results=1000000)
# Export filtered threads
threads = client.search_threads(
project_name="Default project",
filter_string='number_of_messages >= 5'
)Filtering with OQL
Section titled “Filtering with OQL”All search methods accept a filter_string / filterString using the Opik Query Language (OQL):
"<COLUMN> <OPERATOR> <VALUE> [AND <COLUMN> <OPERATOR> <VALUE>]*"- String values must be wrapped in double quotes
- Multiple conditions can be combined with
AND(OR is not supported) - DateTime fields require ISO 8601 format (e.g.,
"2024-01-01T00:00:00Z") - Use dot notation for nested fields:
metadata.model,feedback_scores.accuracy
Common filter examples:
client.search_traces(filter_string='start_time >= "2024-01-01T00:00:00Z"')
client.search_traces(filter_string='usage.total_tokens > 1000')
client.search_traces(filter_string='metadata.model = "gpt-4o"')
client.search_traces(filter_string='feedback_scores.user_rating is_not_empty')
client.search_traces(filter_string='tags contains "production"')
The full list of supported columns per entity type is documented below.
Exporting at scale
Section titled “Exporting at scale”Read operations are rate limited per workspace. The search and listing endpoints used for export — search_traces and search_spans (and the underlying GET /traces and GET /spans endpoints) — are capped at 30 requests per minute per workspace. Exceeding a limit returns 429 Too Many Requests with a RateLimit-Reset header telling you how long to wait. See the rate-limit FAQ for the full list.
That budget is small, so how you fetch matters:
- Fetch in bulk, not item-by-item. A single
search_spanscall streams up to 2,000 rows per underlying request, auto-paginates, and backs off on429, so one call can return thousands of spans without ever erroring. Avoid making one request per trace. - Filter on the server with
filter_string(e.g. a time window) so you only transfer the data you need. - Go easy on concurrency. Limits are shared per workspace, so parallel requests compete for the same budget and hit
429sooner without finishing faster.
from collections import defaultdict

traces = client.search_traces(project_name="Default project", max_results=1000000)

# One call for all the spans, then group them by trace_id in memory.
spans = client.search_spans(project_name="Default project", max_results=1000000)
spans_by_trace = defaultdict(list)
for span in spans:
spans_by_trace[str(span.trace_id)].append(span)traces = client.search_traces(project_name="Default project", max_results=1000000)
# A request per trace: slow, and quickly hits the read rate limit.
spans_by_trace = {}
for trace in traces:
spans_by_trace[trace.id] = client.search_spans(
project_name="Default project", trace_id=trace.id
)REST API
Section titled “REST API”Use the /traces and /spans endpoints to export data. Both endpoints are paginated.
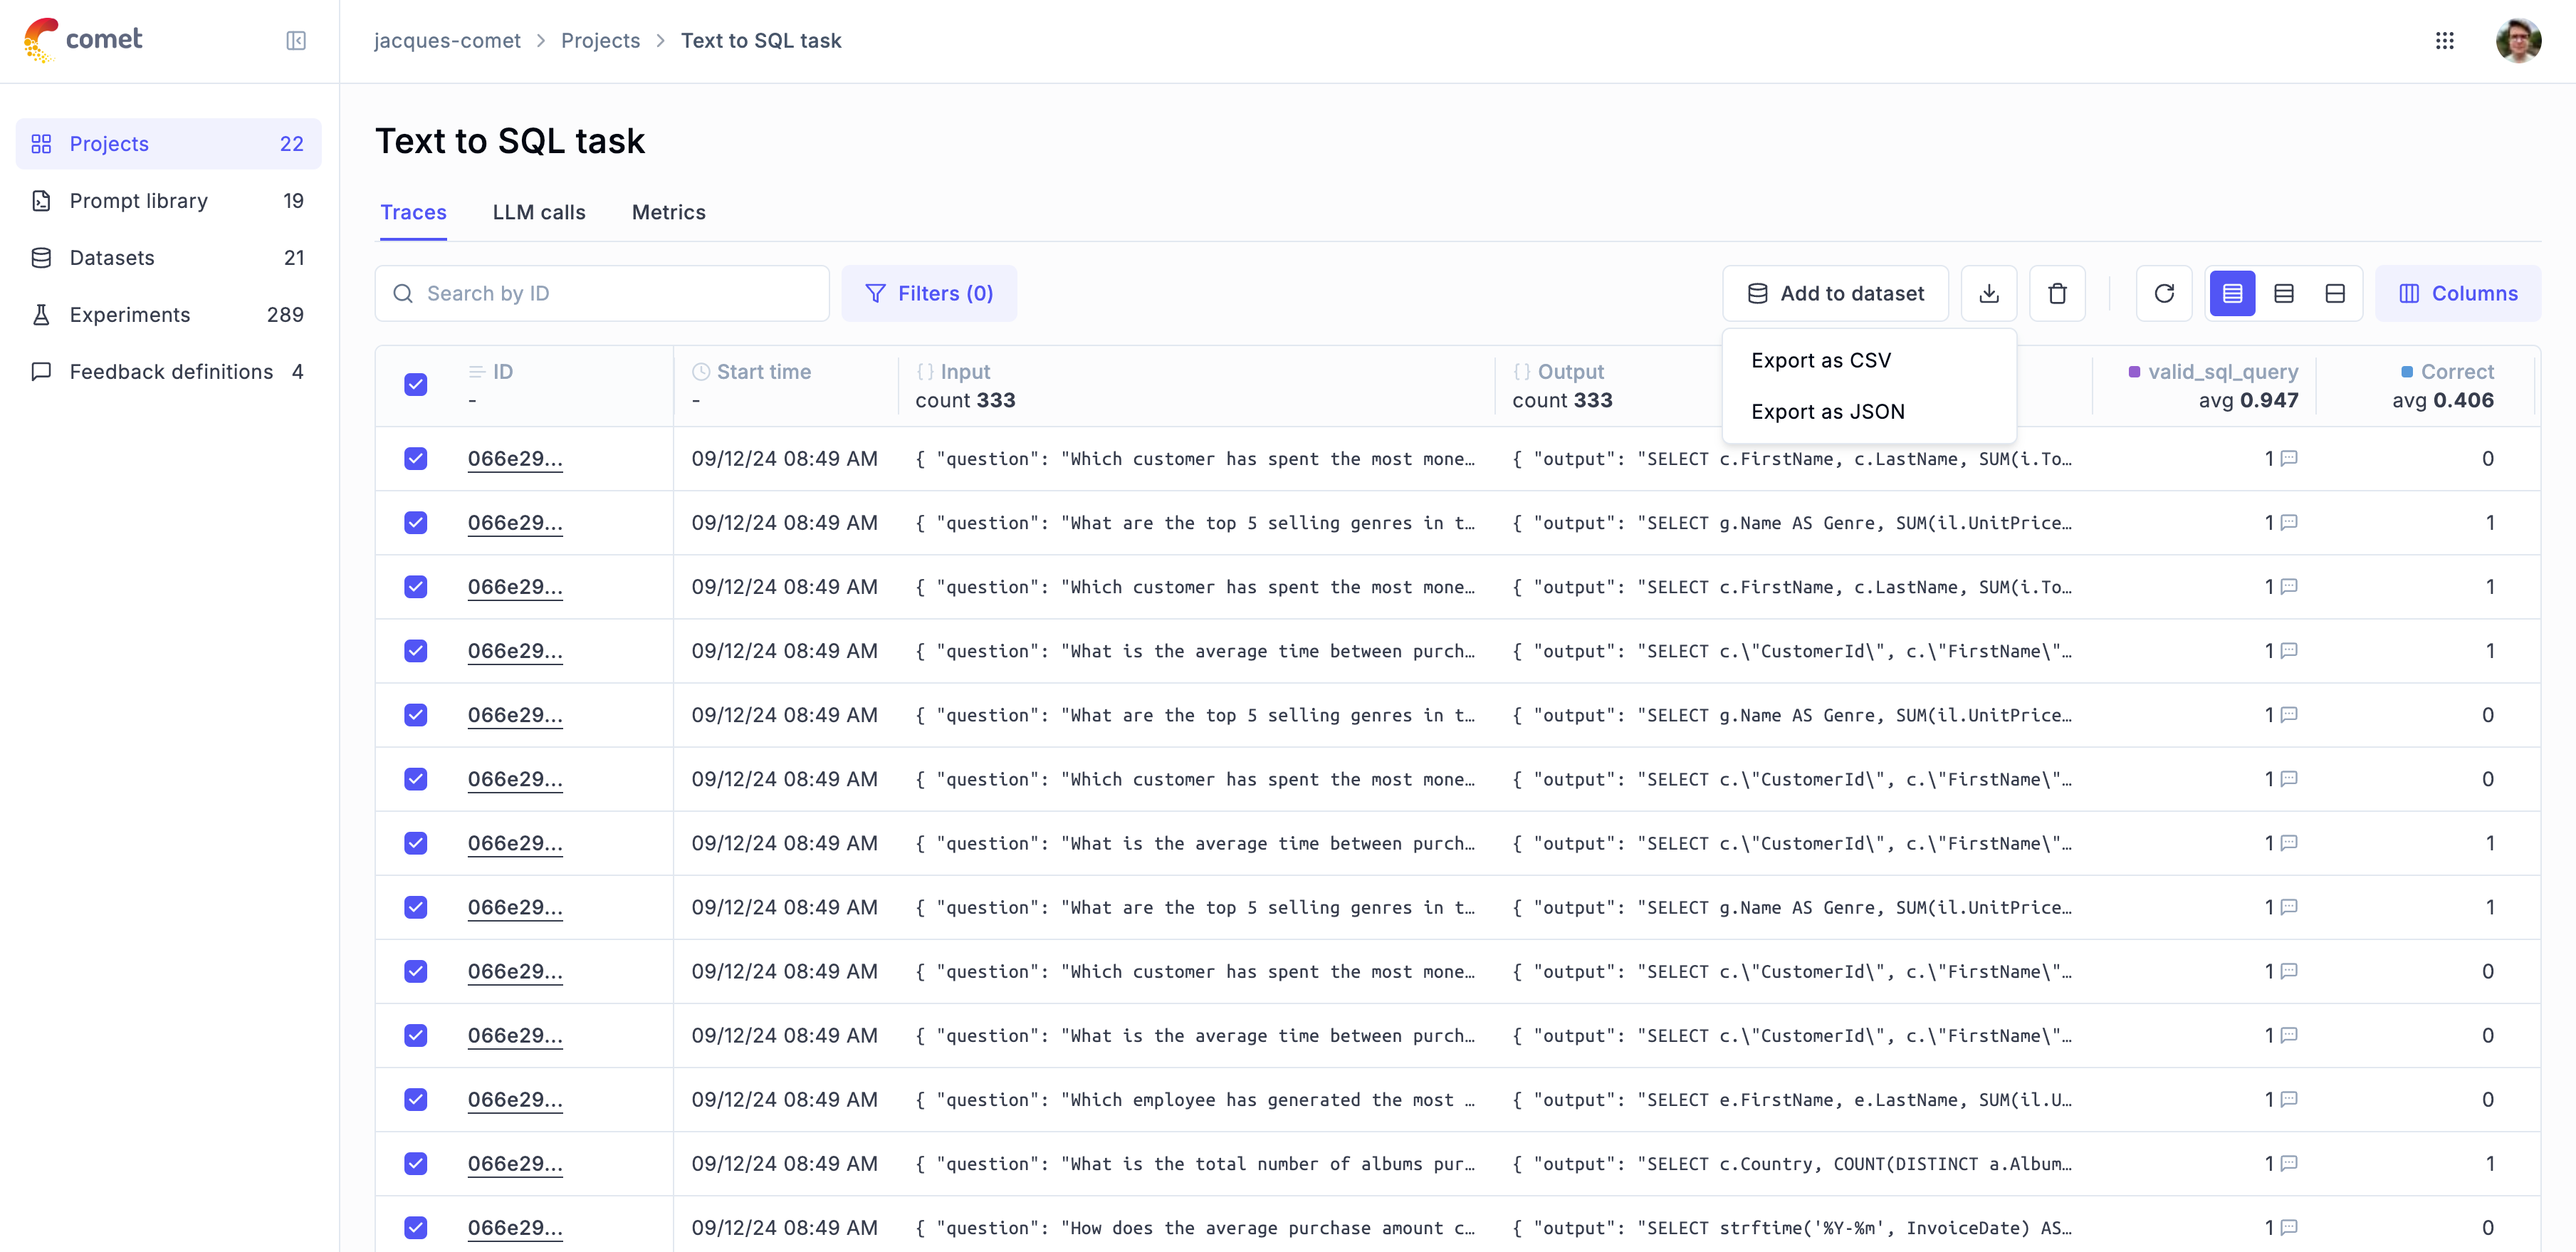
Select the traces or spans you want to export in the Opik dashboard and click Export CSV in the Actions dropdown.
Command-line tools
Section titled “Command-line tools”The opik export and opik import commands let you export traces, spans, datasets, prompts, and experiments for a project to local JSON or CSV files, and import them back — useful for migrations, backups, and cross-environment syncs. Every command is scoped to a single project, named right after the workspace.
On disk, folders and files are keyed by ID: data lands under <path>/<workspace>/projects/<project_id>/, with a project.json ({"id", "name"}) and id-named item files (dataset_<id>.json, prompt_<id>.json, experiment_<id>.json, trace_<id>.json). Human names are stored as data inside the files — this keeps paths free of /, :, and spaces. You still pass project and item names on the command line; the CLI resolves names ↔ IDs for you.
Export
Section titled “Export”opik export WORKSPACE PROJECT ITEM [NAME] [OPTIONS]ITEM is one of: all, dataset, traces, experiment, prompt
# Export everything in a project
opik export my-workspace my-project all

# Export the project's traces
opik export my-workspace my-project traces

# Export a specific dataset
opik export my-workspace my-project dataset "my-test-dataset"

# Export with a date filter
opik export my-workspace my-project traces \
  --filter 'created_at >= "2024-01-01T00:00:00Z"'

# Export as CSV for analysis
opik export my-workspace my-project traces --format csv --path ./csv_data
Import
Section titled “Import”opik import WORKSPACE PROJECT ITEM [NAME] [OPTIONS]WORKSPACE is the source workspace — used to locate the exported files under <path>/WORKSPACE/projects/. Use --to-workspace to write into a different destination workspace.
# Import a dataset
opik import my-workspace my-project dataset "my-dataset"

# Import the project's traces
opik import my-workspace my-project traces

# Preview what would be imported
opik import my-workspace my-project all --dry-run

# Import into a different destination project
opik import my-workspace my-project all --to-project my-restore

# Import into a different destination workspace
opik import src-workspace my-project all --to-workspace dest-workspace

# Import into a different workspace and project
opik import src-workspace my-project all --to-workspace dest-workspace --to-project new-project
The project name is matched against the name recorded in each exported project.json. Import uses the same --path as export (both resolve <path>/<workspace>/projects/<id>/), so no path juggling is needed. Use --to-project <NAME> to import into a different destination project, or --to-workspace <NAME> to import into a different workspace (the source WORKSPACE argument is still used to locate the files on disk).
Imports are automatically resumable — if interrupted, re-run the same command and it picks up where it left off using a local migration_manifest.db.
Imported trace and span IDs
Section titled “Imported trace and span IDs”Imported traces and spans are created under new IDs. The same export can therefore be imported repeatedly, and into any project or workspace, without colliding with the originals — IDs are expected to be unique across an Opik deployment, and much of Opik's behaviour, aggregation included, relies on that.
Nothing else about the trace changes. start_time and end_time keep their original values, span hierarchies and feedback scores are remapped onto the new IDs, and each imported trace records the ID it came from in its metadata as _import_id, so you can map an imported trace back to the source one. Traces are imported in the order the source project listed them, so the destination trace list and thread view keep that order.
A new ID also carries the current time in its UUIDv7 prefix. That matters because Opik validates that an ingested ID's embedded timestamp falls inside an ingestion window around now — 24 hours by default on Opik Cloud — which is what keeps its storage layer partitioned correctly. Minting IDs at import time is what lets you import exported data of any age.
One consequence is worth knowing before a large import: the time-bucketed project metrics key off the ID timestamp, so imported traces are counted at the time of the import rather than when they originally ran. The traces themselves are unaffected — start_time still holds the original time, and filtering or sorting on it behaves as you would expect.
Migrating between environments
Section titled “Migrating between environments”# Step 1: Export from source (use source credentials)
# Writes to ./migration_data/my-workspace/projects/<project_id>/
OPIK_API_KEY=<source_key> OPIK_URL_OVERRIDE=https://source.opik.example.com \
opik export my-workspace my-project all --path ./migration_data
# Step 2: Import to destination — same workspace (use destination credentials)
# Same --path as export — import resolves <path>/my-workspace/projects/<id>/.
OPIK_API_KEY=<dest_key> OPIK_URL_OVERRIDE=https://dest.opik.example.com \
opik import my-workspace my-project all --path ./migration_data
# Step 2 (alternative): Import into a different destination workspace
# WORKSPACE (my-workspace) still locates the files; --to-workspace sets the API target.
OPIK_API_KEY=<dest_key> OPIK_URL_OVERRIDE=https://dest.opik.example.com \
opik import my-workspace my-project all --path ./migration_data --to-workspace dest-workspaceSee the CLI help (opik export --help / opik import --help) for all options and troubleshooting.